I organize my research program around questions that help us navigate the age of data and AI. On the one hand, data analytics, high-performance computing, and AI are opening new paths to scientific discovery. Data from increasingly diverse sources and in new forms are also expanding what we can observe, model, and test. On the other hand, the growing role of data, algorithms, and AI in our lives calls for a scientific understanding of how they reshape knowledge work, economies, and institutions, and what makes these systems effective and trustworthy. My research addresses these challenges by studying how people, information, and algorithms interact in large-scale sociotechnical systems.
 Large-scale sociotechnical systems in the age of data and AI. My research focuses on the challenges of analysis and decision making in large-scale sociotechnical systems, from online platforms and markets to health systems, production networks, and public institutions.
Such systems combine human (social and economic) and machine (algorithmic and AI-driven) processes that shape one another. My work at the intersection of networks, data, and decision sciences is motivated by the need for models and methods that support reliable inference and decision making from complex, often sensitive data about these systems.
 Scalable and resilient operation of these systems depends on our ability to learn their properties from dispersed observations (distributed inference), to influence them through localized actions (decentralized interventions), and to understand how the information available to each participant shapes learning and decision making (information structure).
To support these capabilities, I develop models that explain and predict individual and aggregate behaviors shaped by interactions among people, organizations, and algorithms, accounting for the type and quality of information available to each decision-maker and what others can learn from observing their decisions. Understanding these interactions helps us determine whether information transmission is efficient and guides interventions that rely on information flow, from the adoption of new technologies to public health programs. By modeling these behaviors, my work helps clarify the consequences of policy and institutional choices and guides the design of interventions and platforms for more trustworthy, resilient, and sustainable sociotechnical systems.
 To develop and analyze these models, I draw on network and data sciences, using tools from applied probability, graph theory, statistics and machine learning, algorithms and complexity, and game and decision theory. These tools help me highlight structural features that influence behavior, such as the presence of influential agents, observational and information asymmetries, the topology of data flows, and heterogeneity across individuals and communities. My work spans five connected themes developed in the sections below: learning and collective decisions, privacy and information governance, diffusion and intervention, public health and policy, and resilient systems.
Information, Inference, and Intervention Design for Sustainable and Resilient Sociotechnical Systems
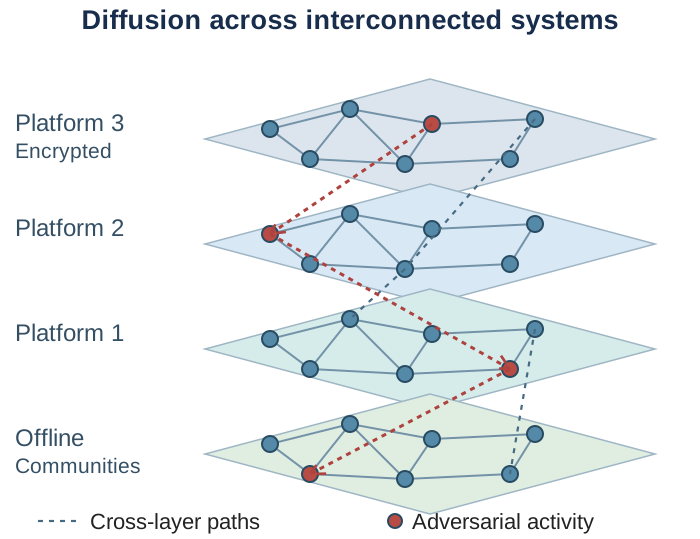
My research examines how behaviors, beliefs, information, and disruptions propagate through social and sociotechnical systems, and how their structures and rules shape collective outcomes. This work ranges from understanding how social contagion, network formation, and online reputation shape business and economic outcomes in online markets, crowdsourcing platforms, and the sharing economy, to examining how network interactions affect knowledge sharing and aggregation, population health, and the resilience of production networks and public institutions. A central question across these settings is how people and institutions can learn and act effectively when these systems are only partially observable, strategically shaped, and constrained by privacy, security, and information-governance concerns.
I approach this challenge through four complementary angles: how differences in what each actor knows shape individual decisions and collective outcomes (information asymmetries); how large systems can be understood from dispersed and partial observations (distributed inference); how they can be influenced through localized and resource-constrained interventions (decentralized interventions); and which structures let them absorb shocks and sustain their capacities over time, from containing cascading failures to preserving human expertise and the growth of shared knowledge (resilience and sustainability). Two foundational processes are central to this work: contagion, through which behaviors, information, and failures spread across connections [1.1–1.11], and learning, through which individuals, firms, and other actors combine their own information with signals they receive from others [1.12–1.22]. I discuss these learning questions in more detail in the Group Decision Making, Social Learning, Distributed Inference, and Collective Intelligence section below.
Methodologically, I combine probabilistic analysis of network dynamics with the design and analysis of algorithms for learning and intervention. I use percolation theory and asymptotic analysis to characterize how network structure shapes contagion [1.1] and resilience to supply disruptions [1.9]. My algorithmic work develops performance guarantees and characterizes the limits of learning and intervention, examining how data availability, computational demands, and privacy constraints shape what can be achieved [1.3, 1.6, 1.7, 1.15, 1.16, 1.19]. I use game theory and dynamical systems to study when individual incentives undermine collective performance, and how information and institutional design can shift equilibria toward more desirable outcomes [1.10, 1.17, 1.23]. To connect these models to data, I use simulation-based inference when likelihoods are intractable [1.14], and develop metamodels and sequential sampling methods to study how systems evolve and respond to interventions when population-scale simulations are costly [1.24–1.27]. For network data, I use topological and statistical methods to construct and estimate measures of connectivity and diffusion, including under privacy constraints [1.2, 1.8, 1.28, 1.29].
My work on privacy and public health (described below) builds on these questions in two connected directions: designing interventions that improve population health, and enabling useful inference and decision making while protecting individual privacy. The effects of public health policy depend on spillovers between connected populations and on how norms and beliefs spread [1.8, 1.12, 1.13, 1.23, 1.28]. Evaluating these interventions also requires estimating how their benefits vary across communities under limited simulation budgets [1.24, 1.25, 1.27, 1.30]. Privacy becomes a sociotechnical design question when the networked data that make inference and targeting possible also put people at risk [1.6, 1.7, 1.15]. The design of these protections can itself reshape learning dynamics and strategic equilibria, sometimes improving collective outcomes [1.17, 1.18].
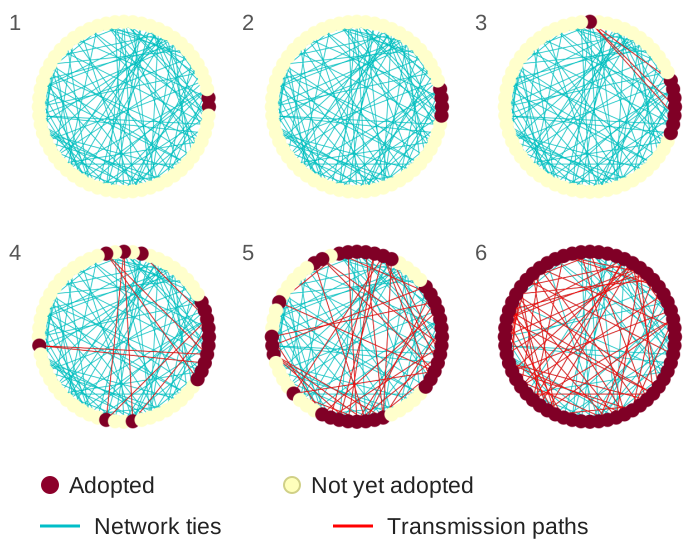
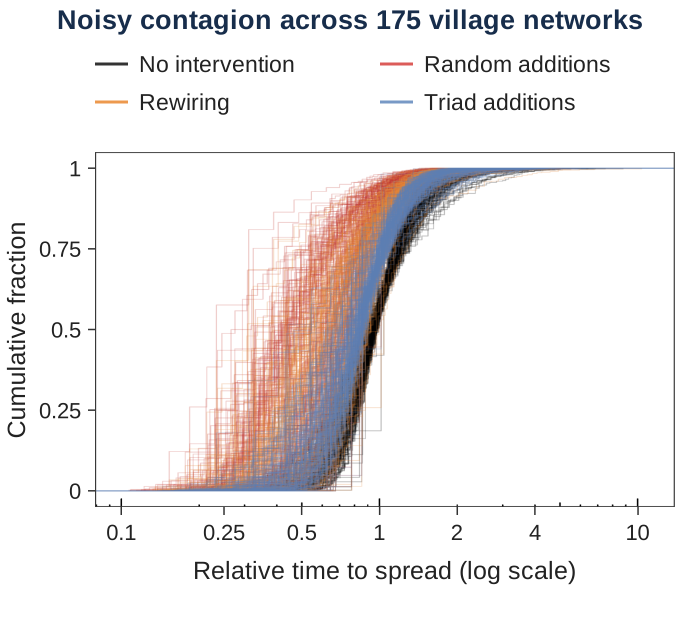
long ties and noisy complex contagions
In [1.1], we revisit a “weakness of long ties” for complex contagions, which need reinforcement from several adopting neighbors, unlike simple contagions that can pass through a single contact. Analyzing circular lattices with rewired edges, we show that a small probability of adoption below the threshold is enough for random rewiring to accelerate spread. This holds in simulations on empirical networks, with partial but frequent enough rewiring, when adoption decisions are reversible but infrequently so, and in high-dimensional lattices. The work continues in two directions: using extended persistent homology to tell simple and complex contagions apart in observed diffusion patterns [1.2], and studying multi-state bootstrap percolation in neuronal networks, where weakly active states play a role analogous to below-threshold adoptions in lowering the connectivity needed for spread.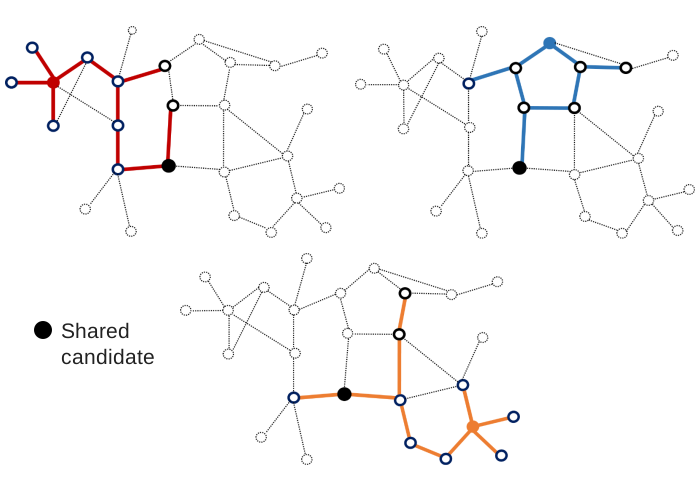
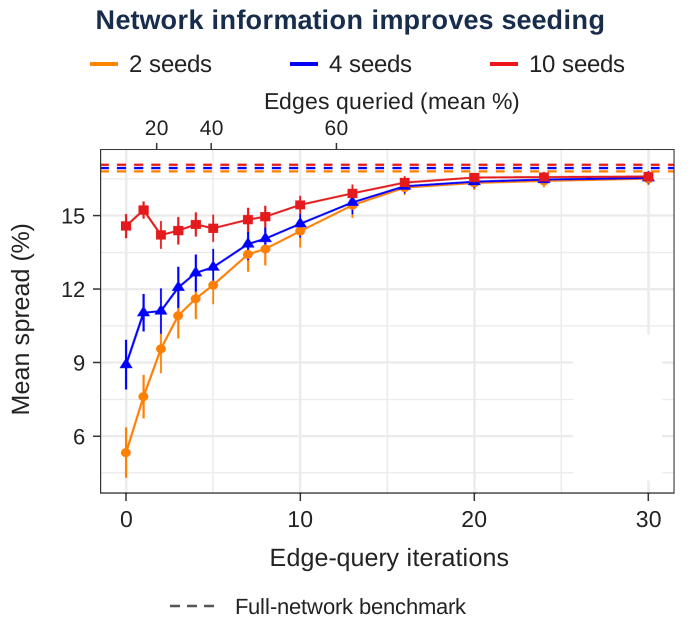
seeding with costly network information
In [1.3], we choose k seeds to maximize the expected spread of a contagion when learning the network is itself costly; most work on influence maximization assumes the entire network is known. We give polynomial-time algorithms that query only a bounded part of the network and achieve almost tight approximation guarantees, with lower bounds on the number of queries that quantify the value of network information for seeding. Follow-up work extends the framework to time-critical interventions in which collecting network data itself takes time [1.4, 1.5], and to sensitive networks, where seeds must be chosen from privacy-protected information [1.6, 1.7].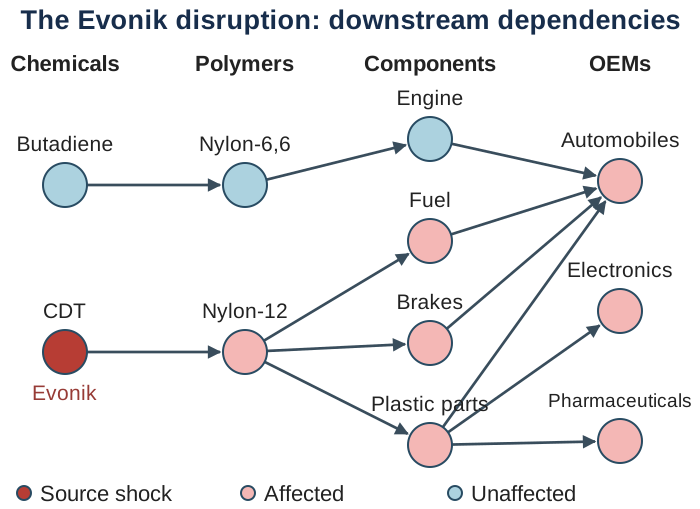
structural resilience of production networks
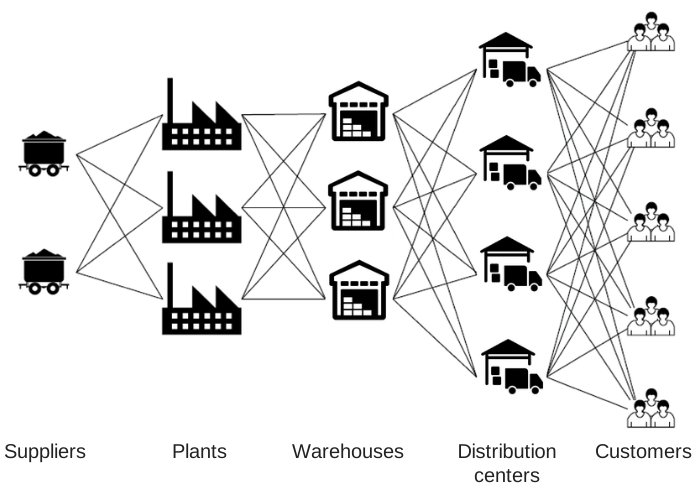
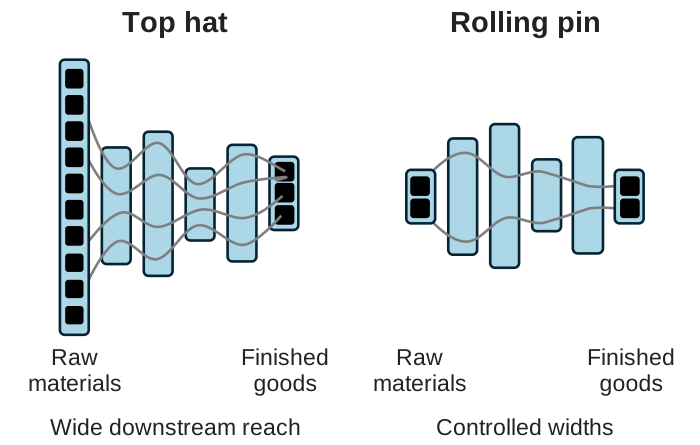
In [1.9], we use a node-percolation model to study how supply disruptions trigger cascading failures: products fail when all their suppliers are disrupted, and these failures propagate to downstream products that depend on them. We define resilience as the largest supplier failure rate a network can sustain while maintaining aggregate production. We identify structural features that shape this resilience, including the numbers of raw materials and finished goods, how many inputs each product requires, how many other products depend directly on it, and the length of production chains. “Top hat” architectures are fragile because a disruption to a single raw material can cascade through a large fraction of products. “Rolling pin” architectures keep the number of products exposed to any one disruption limited even as the network grows, allowing them to absorb shocks while maintaining aggregate production. We complement these structural results with a scalable linear program that approximates cascade sizes in large supply networks whose interdependencies make exact calculations computationally prohibitive. In [1.31], we explore how product and supply chain co-design can be formulated as a robust stochastic optimization problem that accounts for supply disruptions.
democratic resilience and sociotechnical shocks
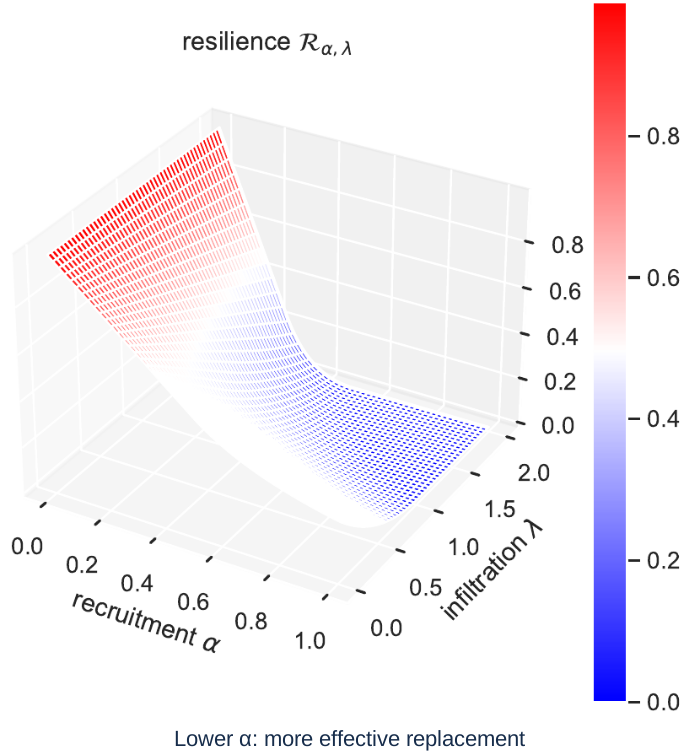
In [1.10], we offer an explanation for cascading attrition among election officials: when harassment is spread over those who remain, each departure raises the pressure on the rest, and the system can unravel. Differences in officials' tolerance create fragility that adversaries can exploit, especially once social media make harassment cheap and easy to target, but they also let limited, localized interventions, such as salary incentives and targeted efforts to raise turnout, deliver significant improvements in democratic resilience.
harmful content on private messaging platforms
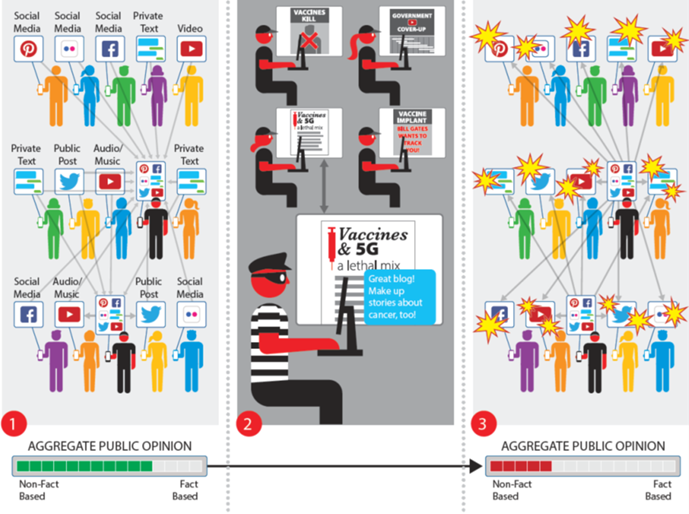
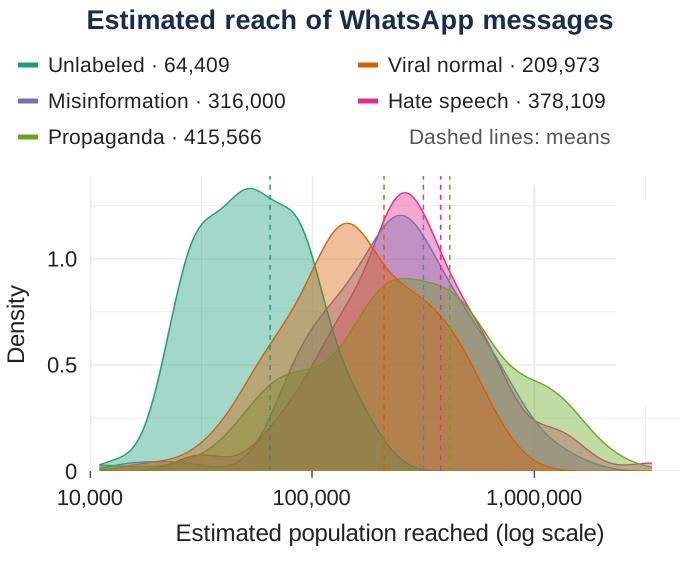
In [1.11], we reconstruct message cascades from a dataset of over 5.1 million messages across about 6,000 WhatsApp groups in India and find that harmful messages spread deeper and wider than other messages. We estimate that harmful viral content reaches roughly five times as many users as unlabeled messages. These findings suggest that interventions targeting message re-sharing could help limit the spread of harmful content on private messaging platforms.
Contagion and learning now unfold in systems where AI shapes what people see, learn, and decide, and where AI agents increasingly act alongside people. The foundational questions above resurface in these systems as well. I am particularly interested in how AI reshapes the knowledge economy, including collective learning and coordination across knowledge communities, online platforms, and markets. This includes how people and AI agents create and verify knowledge, how human expertise develops through these interactions, and how attention, knowledge work, and resources are allocated under uncertainty and competing incentives. These questions also motivate my interest in identifying systemic vulnerabilities that arise from these interactions and improving the rules governing information exchange and coordination. The aim is to sustain trustworthy knowledge and collective learning in systems that protect privacy and enable inclusive participation, while retaining the capacity to adapt and recover from disruptions.
See here for a list of the relevant publications.
Privacy of Interconnected Learning Systems and Operations
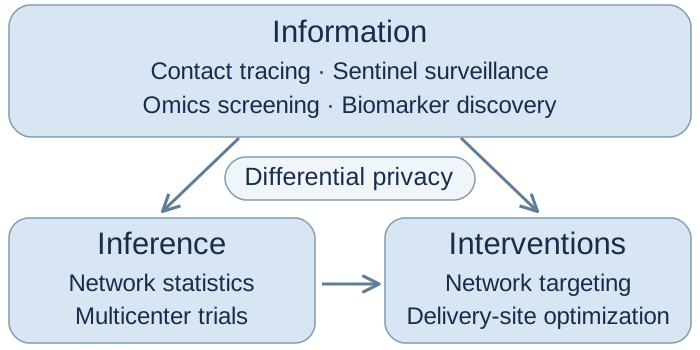

The data most useful for learning, coordination, and intervention are often the most sensitive, distributed across parties, strategically withheld, or only partially observable. This work asks how organizations and platforms can still estimate, decide, and intervene well under those constraints. It treats privacy as a design principle rather than only a constraint on data use, and in some settings as a design instrument that improves how a system operates.
In [2.1], we argue for building this kind of protection into networked healthcare by design, across the data lifecycle from collection to inference to decisions, so that lawful, trustworthy data sharing becomes the default rather than a barrier to overcome. The annotated reading list Yuxin Liu and I wrote [2.2] offers an entry point to where privacy meets incentives, data acquisition, and operational decisions; it followed a tutorial we organized with Marios Papachristou and Juba Ziani.
-


learning and inference from private, distributed data
In [2.3], we study how agents in a network estimate shared statistical quantities from privately held data while protecting both their observations and, in some settings, their local connections. The aggregation rules add calibrated noise and converge in finite time; among mechanisms of this kind, Laplace perturbation gives the best convergence for a fixed privacy budget. The analysis makes precise a trilemma among privacy, communication, and decision quality, and the methods are validated on U.S. power-grid and German household electricity data.In [2.4], we extend from continuous estimation to discrete inference and hypothesis testing, with distributed maximum-likelihood protocols applied to multicenter clinical-trial survival analysis and federated genomic biomarker discovery under false-discovery-rate control. Because institutions exchange only privatized summaries rather than patient records, this lets smaller and more diverse hospitals join multicenter studies that data-sharing agreements would otherwise delay or prevent.
-


privacy, incentives, and strategic information sharing
In [2.5], we study how people learn from others’ choices when privacy limits what those choices reveal about their private signals. Even without privacy constraints, later participants may follow the crowd rather than their own information, allowing mistaken beliefs to persist through information cascades. Carefully designed privacy-preserving randomization can weaken fragile cascades and improve collective learning. For example, different flip rates under true and false states can help later learners distinguish the two states, accelerating learning despite the added noise.In [2.6], we study why competing firms may withhold data even when pooling it improves their forecasts. Privacy noise limits what rivals can learn from a firm’s contribution, softening the competitive pressure created by sharing—but also making the pooled information less useful. External signals supplied by the platform preserve the informational benefit: privacy protection and external signals act as complements to make voluntary data sharing worthwhile when either alone is insufficient.
-
targeted interventions on sensitive networks
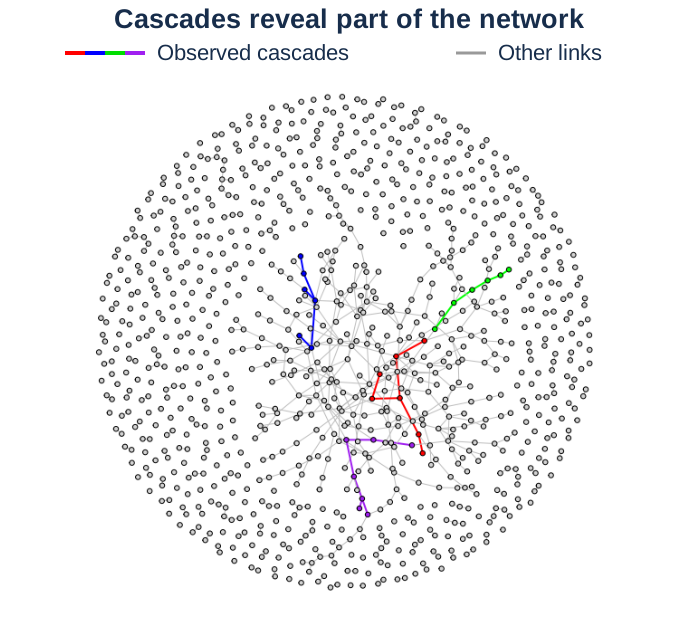
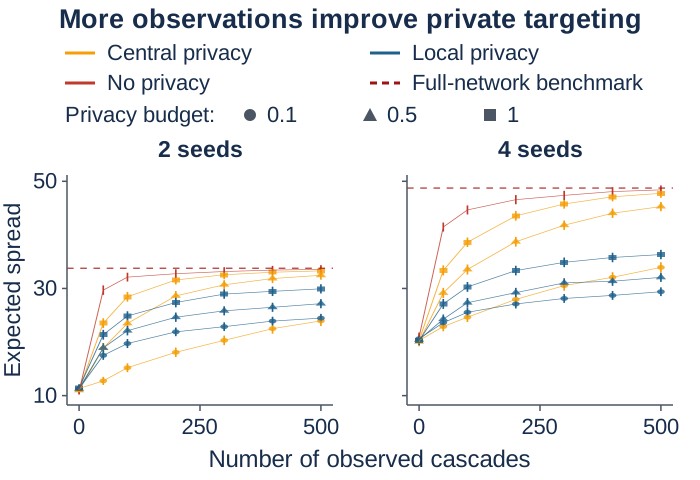
In [2.7, 2.8, 2.9], we design targeted network interventions when the network is itself sensitive, only partially observed, or too costly to reconstruct, motivated by HIV prevention and PrEP delivery. Partial network information and contact-tracing-style cascade data can still support effective seeding while protecting the people involved.The work frames and resolves a second trilemma: the cost of acquiring network information, the benefit of sharper targeting, and the privacy risk of using personal data. Results come from empirically grounded simulations of sexual-activity networks, and they extend our earlier seeding work under costly network information [1.3] to the privacy setting.
-


private measures of network structure
In [2.10], we release measures of assortative mixing and connectedness, capturing whether edges tend to link similar nodes and how connected the network is, while protecting both the edges and sensitive node attributes. These indices resist direct privatization because a node's attribute can influence the index across the whole network, so protecting it naively forces large, compounding noise that degrades the estimates.We instead use a two-stage privatize-then-debias procedure, adding noise for the guarantee and then correcting the bias it introduces, with consistency and asymptotic normality for the released statistics.
-


mechanisms shaped by the geometry of the data
In [2.11], we introduce Conformal-DP, a density-aware mechanism for data lying on curved spaces (Riemannian manifolds), rather than in flat coordinates. Using a conformal transformation, we match the perturbation to the local data density to improve the privacy–utility trade-off for heterogeneously distributed, non-Euclidean data. This opens new opportunities to design privacy noise mechanisms for structured data objects such as networks, manifolds, embeddings, and genomic sequences, whose geometry can be distorted by coordinate-wise noise.
My third Ph.D. student, Yuxin Liu, built his dissertation, Privacy-Preserving Information Design for Learning, Strategic Interaction, and Networked Platforms, on the sequential-learning, information-sharing, private-seeding, and connectedness-index results described above, treating privacy as a design dimension that shapes how information is collected, shared, and analyzed across learning, strategic, and networked settings.
Sensitive data must often be shared and analyzed to advance health and social science and to support better policy, while the same data can create risks to privacy, dignity, self-determination, and protection against bias and discrimination. The direction I am most focused on is designing protection around the way people are connected and systems operate, through contagion, social ties, social learning, or shared genetics, rather than treating privacy as a cost imposed from outside. Designed this way, protection can shield sensitive dependencies while preserving the quantities required for inference and operational decisions; for example, improving association tests on network and individual-level data by attenuating spurious dependence, or keeping assignment and matching decisions near-optimal while sensitive attributes stay protected.
See here for a list of the relevant publications.
Public Health Dynamics, Operations and Policy
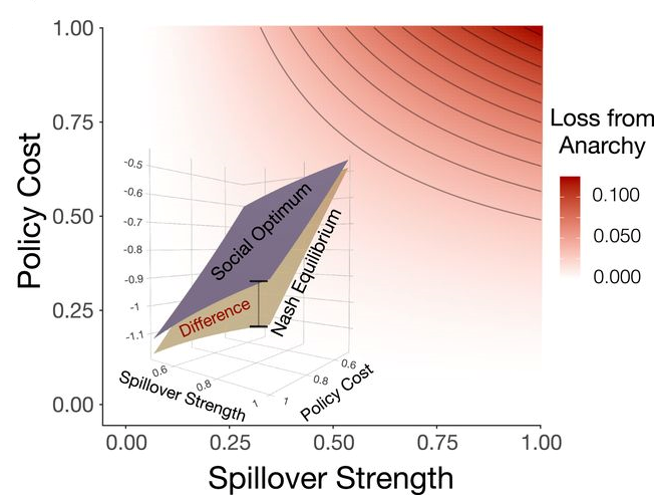
My research in public policy and population health builds on the work on social contagion and network diffusion described above. My entry into public health came through the COVID-19 pandemic, where I became interested in how policy effectiveness depends not just on where a policy applies but on how its effects travel through social networks, via spillovers between connected populations, behavioral responses, and the diffusion of beliefs. The work since then has developed along two complementary lines: measuring how health risks and protective policies propagate through socio-spatial networks, and building computationally tractable methods for evaluating interventions when the underlying simulations are expensive.
 policies, norms, beliefs, and behavior during COVID-19
This line of work began during my postdoc at MIT. With Dean Eckles, Sinan Aral, and colleagues, we studied spillovers in mobility and social distancing across socially and geographically connected U.S. regions, showing the cost of uncoordinated policy responses [3.1]. We then fielded a global survey in 67 countries with more than two million responses on COVID-19 beliefs, behaviors, and norms [3.2], and ran a preregistered randomized experiment with nearly half a million participants across 23 countries showing that accurate descriptive-norm information increased intentions to accept a COVID-19 vaccine [3.3].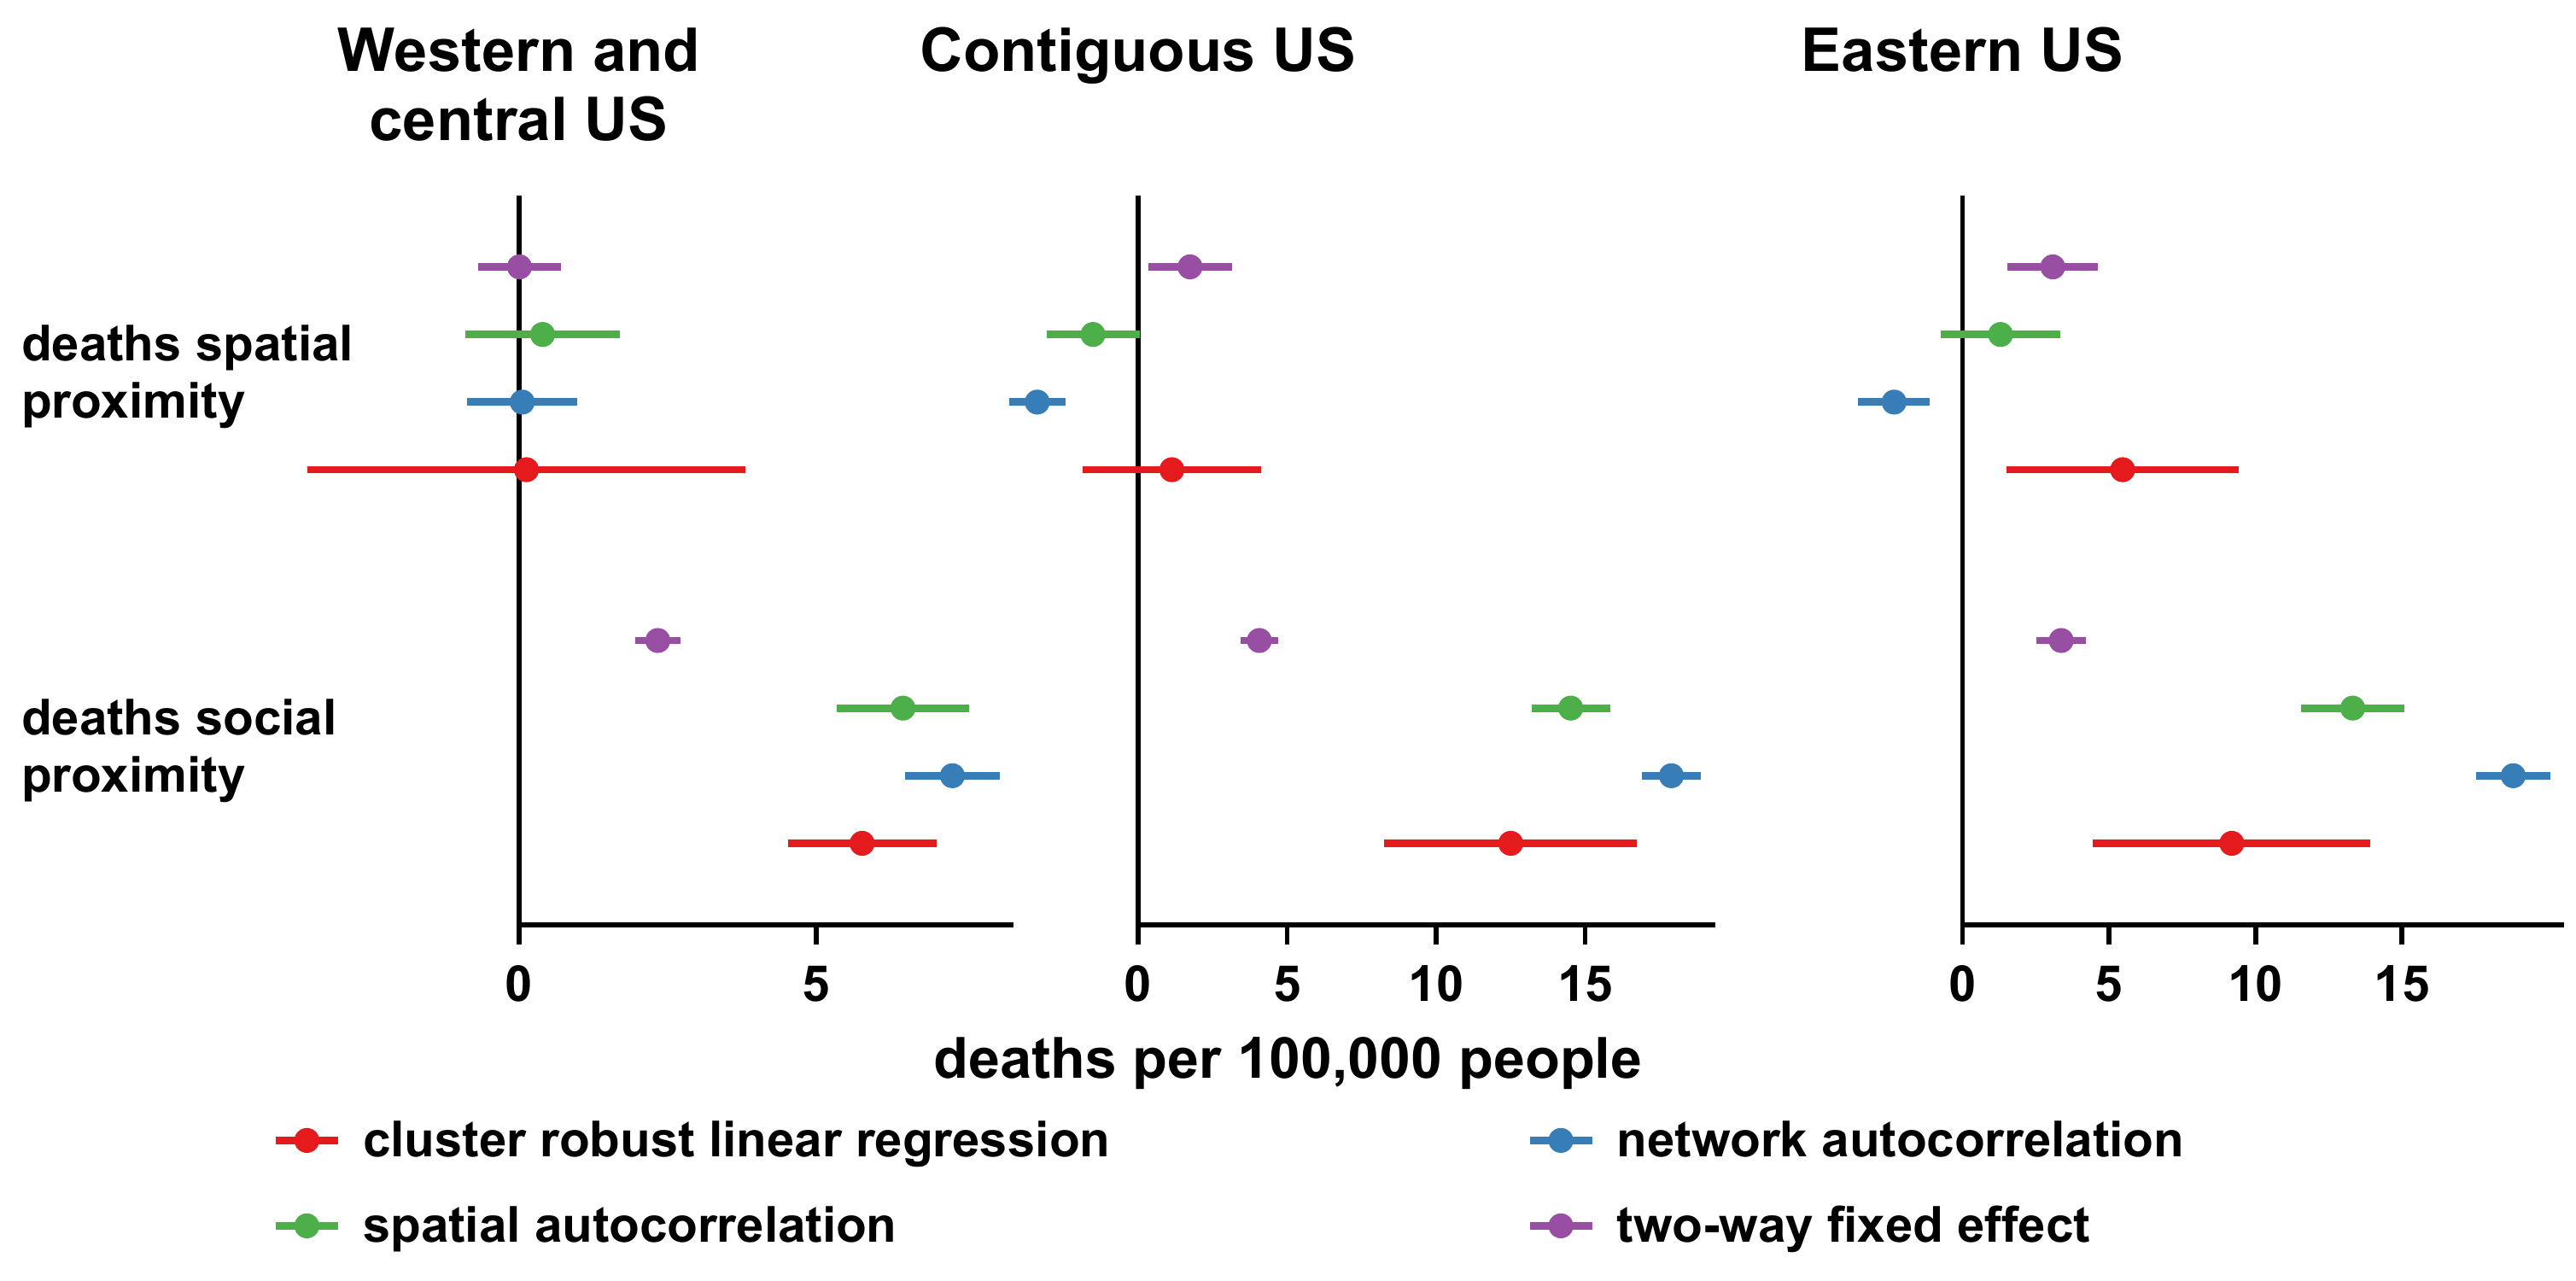 social networks and opioid overdose mortality
In [3.4], we ask whether opioid overdose mortality is shaped by social ties. Social and geographic proximity are strongly correlated, so measuring social influence means separating the two: using Facebook's Social Connectedness Index we build a network-weighted exposure measure and estimate its association with county overdose mortality, controlling for mortality in spatially proximate counties and for demographic and clinical covariates. A one-standard-deviation increase in deaths in social proximity is associated with thirteen additional deaths per 100,000 population in the contiguous United States. The social association remains statistically significant across a range of alternative model specifications (network and spatial autocorrelation models, two-way fixed effects, two-stage least squares), while the spatial association does not hold consistently.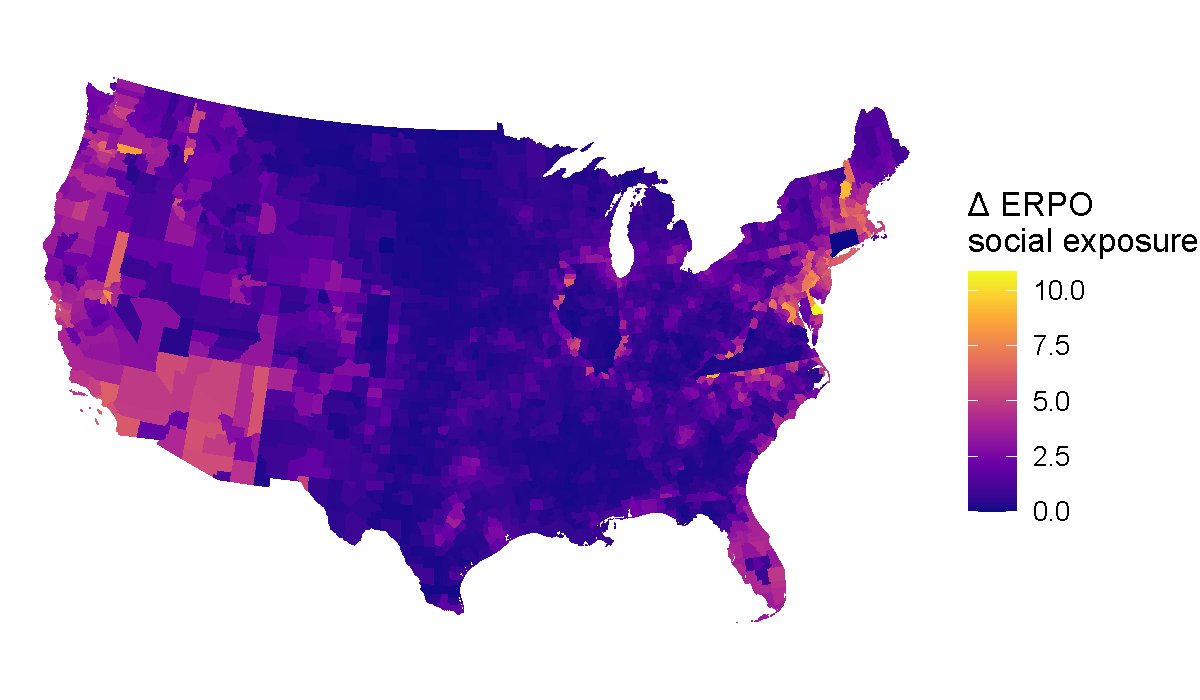 socio-spatial dynamics of suicide and firearm policy
In [3.5], we apply the same design to county suicide mortality over 2010–2022. A one-standard-deviation increase in the suicide rate of socially connected counties is associated with about 2.8 additional suicide deaths per 100,000 people. Extreme Risk Protection Orders are state laws that temporarily restrict firearm access for people at risk of self-harm; a one-standard-deviation increase in social exposure to ERPO-implementing states is associated with about 0.2 fewer suicide deaths per 100,000, even where the policy is not locally enacted, and persists under geographic and state-by-year controls. Harmful exposures and protective policy appear to diffuse through the same social ties, which argues for prevention strategies that account for network structure alongside conventional geographic targeting.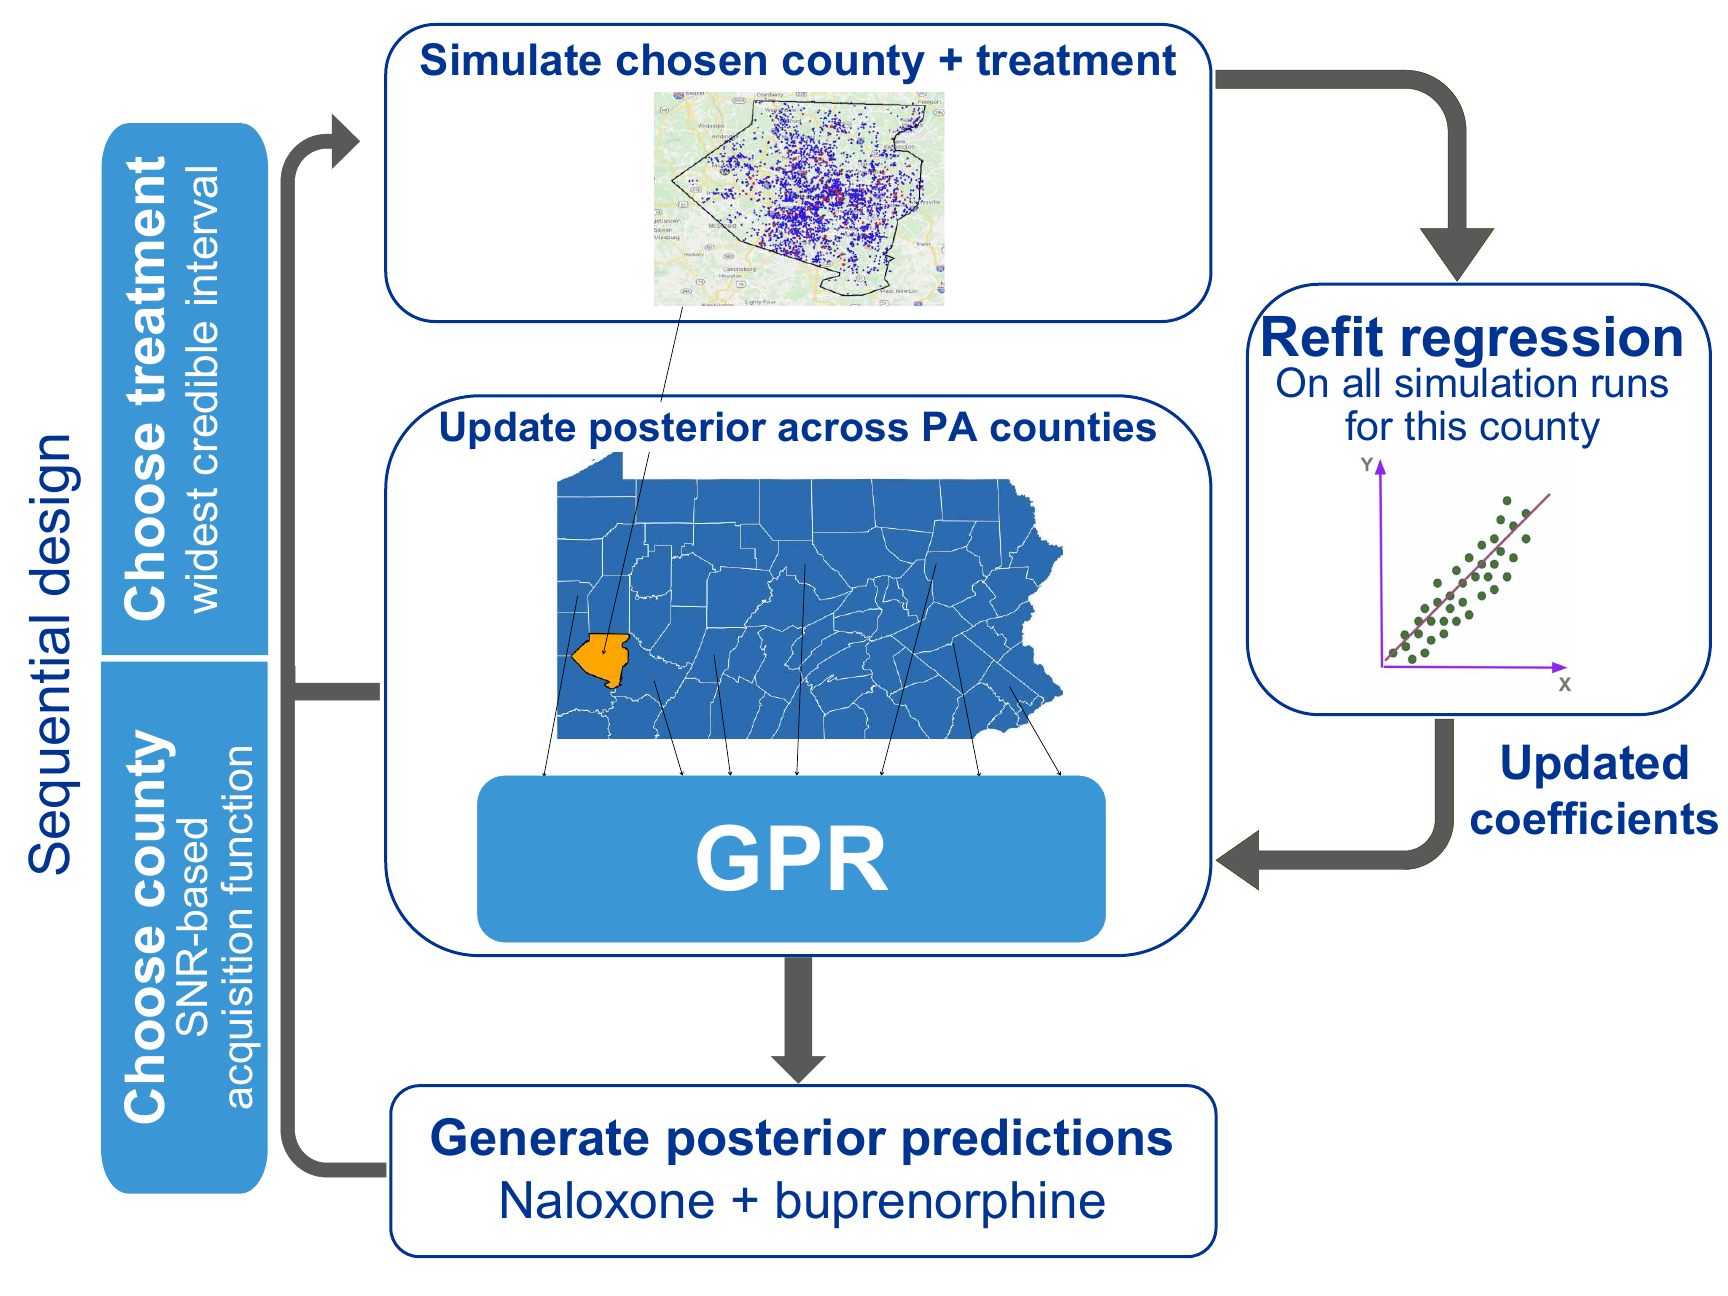 policy evaluation with costly simulations
Population-scale agent-based models of opioid use disorder are costly to run, which makes systematic policy comparison difficult. In [3.6] we allocate simulation runs across treatment conditions by confidence-interval width, matching uniform sampling's accuracy with far fewer runs, and in [3.7] we identify which estimator to prefer at a given budget. In [3.8] we show Gaussian process regression can recover how two diseases spread differently across space from simulated populations alone. In [3.9] we pair a Gaussian process that learns how treatment effects vary across counties with a response function that maps intervention levels to mortality, and a two-step sequential design that chooses which county and intervention combination to simulate next; for Pennsylvania counties this reaches under 5% average relative error using fewer than 2% of the runs an exhaustive design would require.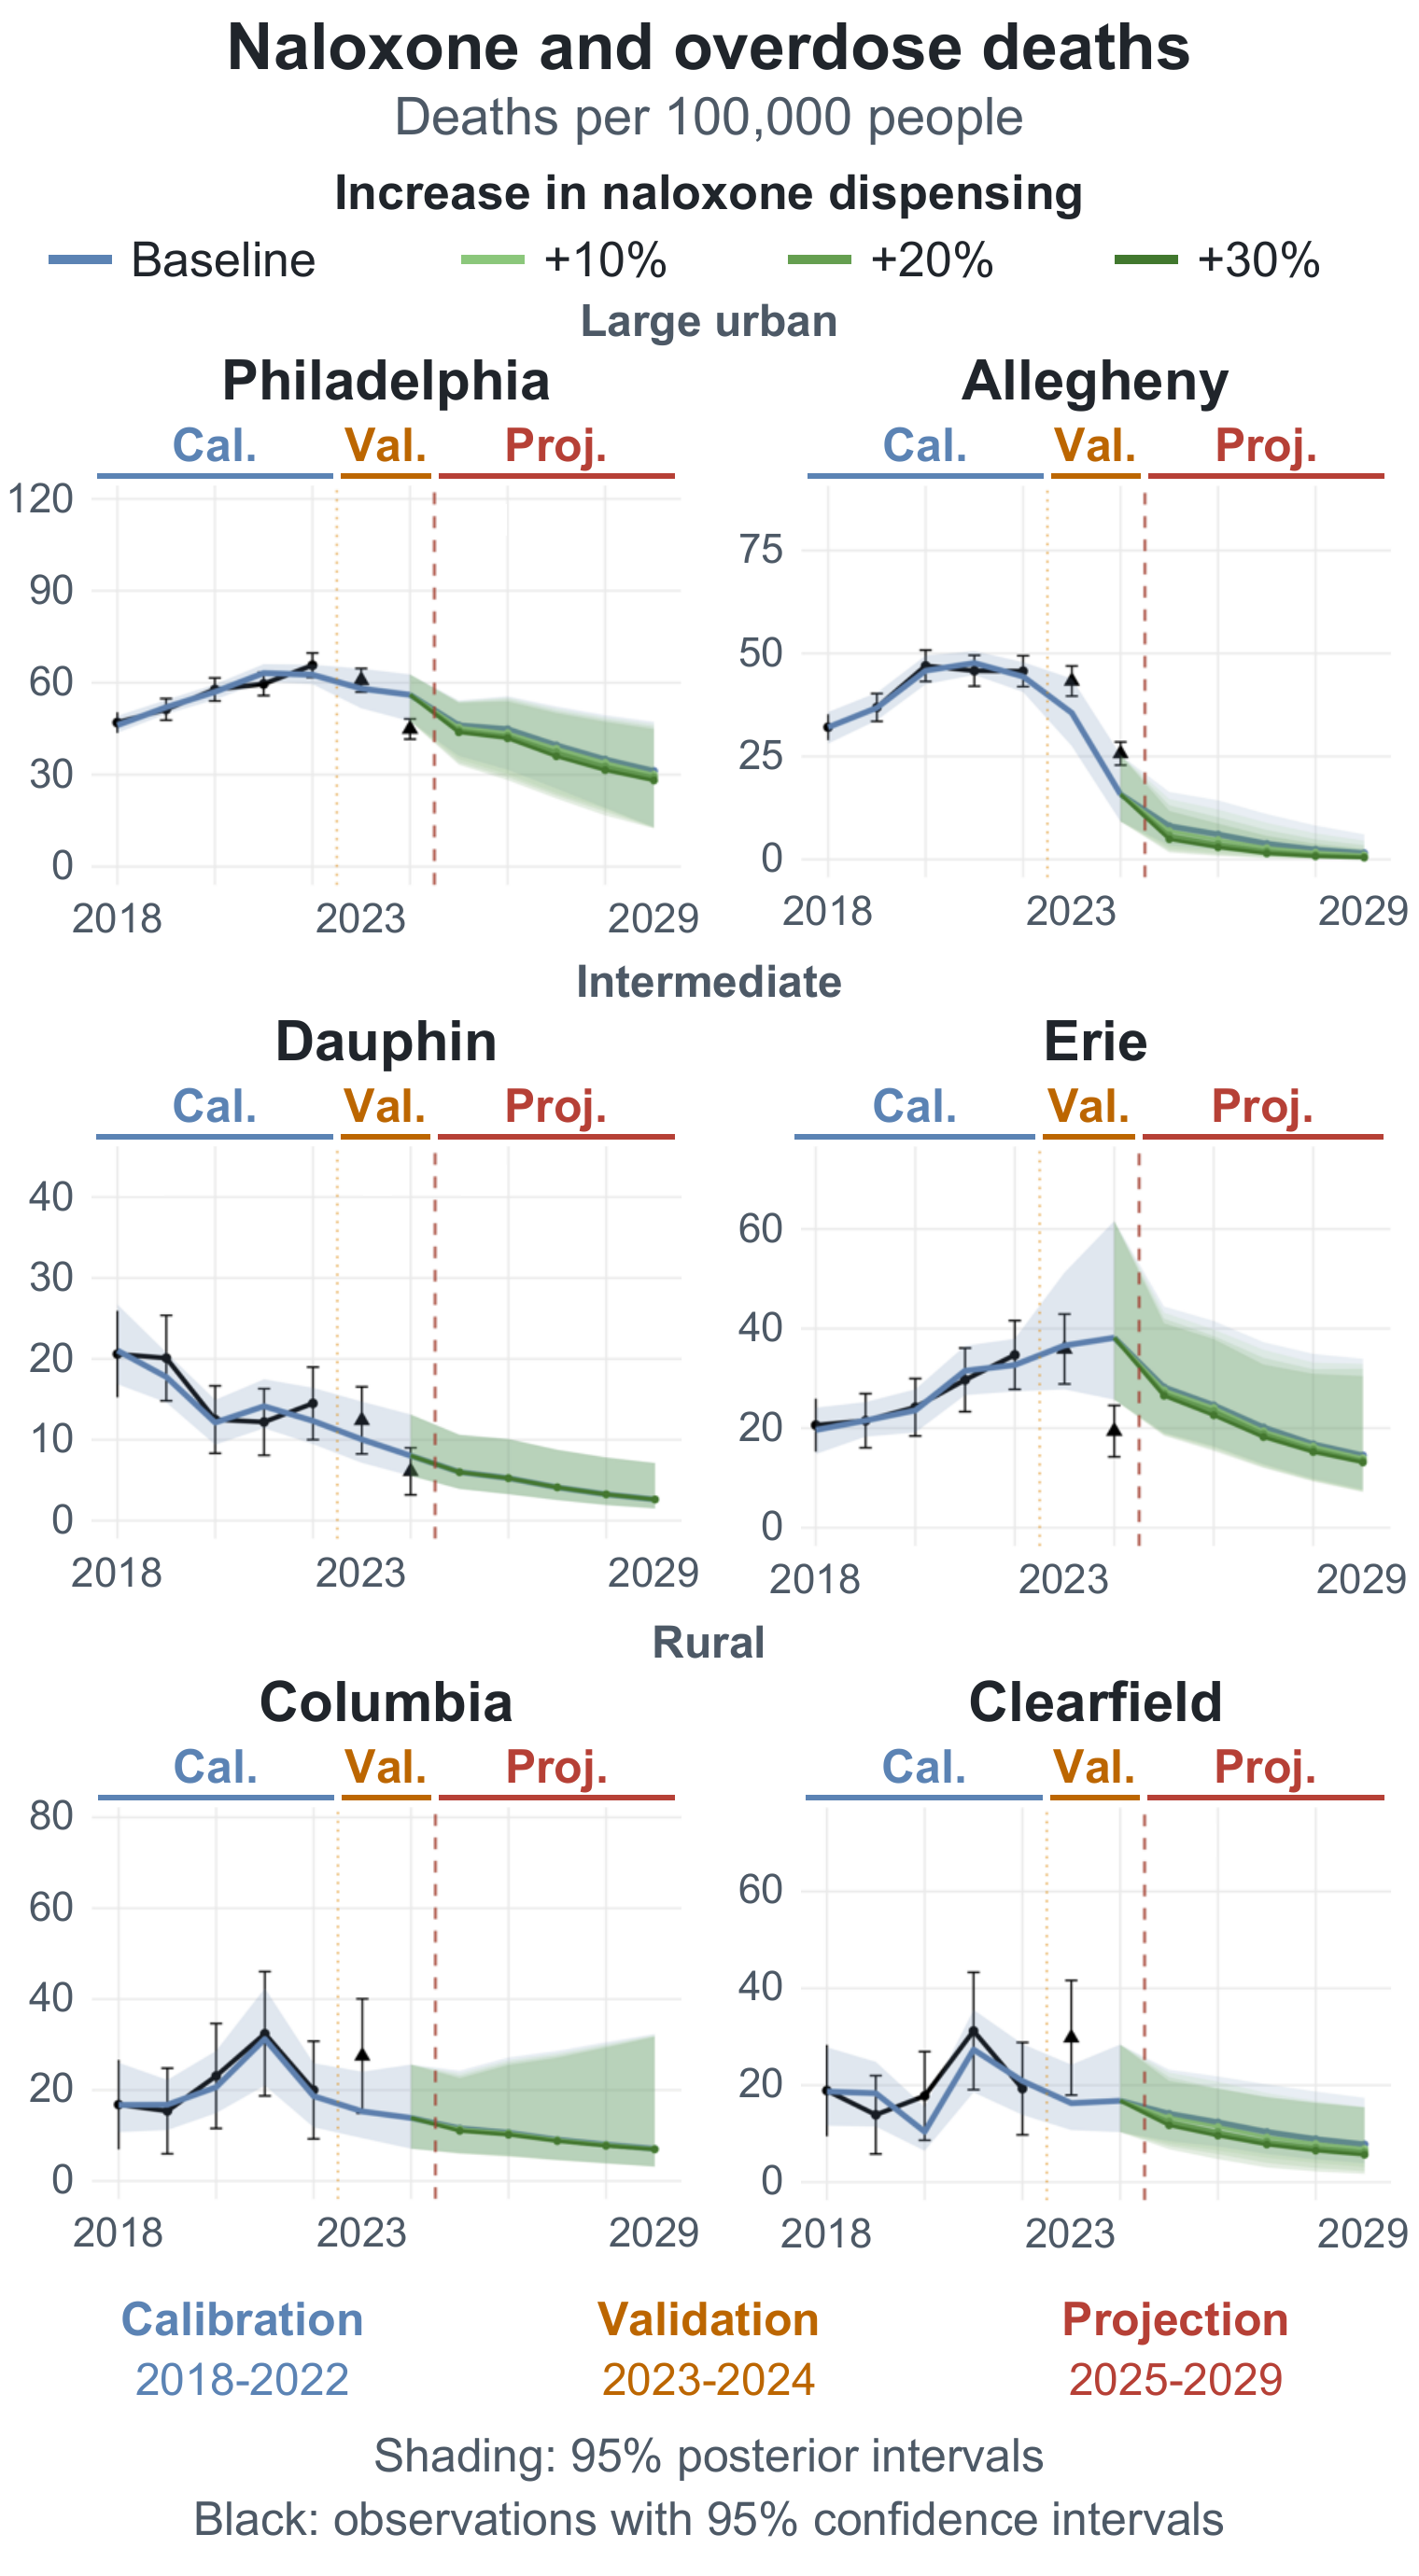 county-level heterogeneity in harm reduction and treatment
In [3.10], we calibrate a Markov model of opioid use disorder separately to six Pennsylvania counties spanning urban, intermediate, and rural settings, and project overdose mortality for 2025–2029 under separate and combined increases in naloxone and buprenorphine dispensing relative to each county's projected baseline. A 30% increase in naloxone dispensing is projected to reduce the 2029 overdose death rate by roughly 70% in Allegheny County but about 14% in Erie, compared with the no-increase baseline. The intervention with the larger projected benefit also varies by county: naloxone produces a larger reduction in Allegheny, while buprenorphine produces a larger reduction in Erie, supporting locally tailored harm reduction and treatment planning.
My first Ph.D. student, Kushagra Tiwari, developed the socio-spatial mortality studies in his dissertation, Socio–Spatial Network Dynamics of Public Health Crises in the US, which measures network-mediated exposure through county-to-county social ties, separately from geographic proximity, for both mortality risks and protective policies. My second Ph.D. student, Abdulrahman Ahmed, developed the simulation-based evaluation methods in his dissertation, Computationally Efficient Simulation-Based Policy Evaluation for Epidemic Interventions: Metamodeling, Sequential Design, and Localized Effect Estimation, toward a vision of precision public health: policy evaluation that is local, computationally tractable, and designed for heterogeneous populations.
The unifying goal across these works is to make computational public health more adaptive and actionable: to transform heterogeneous, networked, and partially observed health data into models that can guide timely, equitable, and locally tailored policy and operational decisions. This includes optimizing screening and surveillance policies and operations, using health economics and value of information analysis to guide data collection and resource allocation. I am particularly interested in applying these methods to adolescent substance use and the co-epidemics of suicide and substance use.
See here for a list of the relevant publications.
Group Decision Making, Social Learning, Distributed Inference, and Collective Intelligence
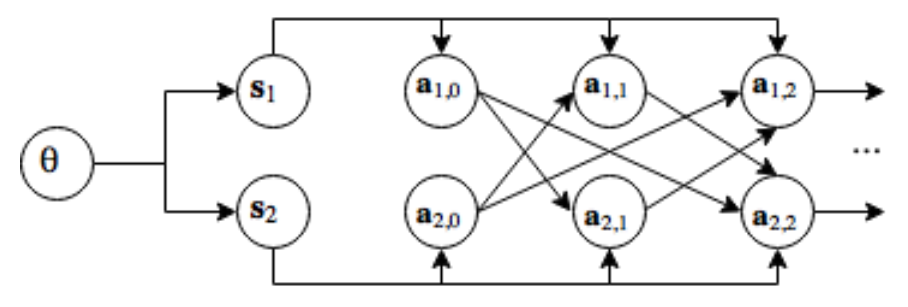
In my Ph.D. dissertation, I studied the purely informational interactions of individuals in a group, where they receive private information and act based on that information while repeatedly observing each other's beliefs or actions. Such situations arise, for example, in jury deliberations, expert committees, and medical diagnoses. I developed parallel theories of group decision making following Bayesian and non-Bayesian approaches. In the Bayesian setup, I characterized computational barriers and investigated special structures in which computations simplify. In the non-Bayesian framework, I proposed the no-recall model to reconcile existing heuristics for belief formation and decision making in groups. An overview of these foundations appears in [4.1].
The following are some highlights from my research on group decision making and social learning:
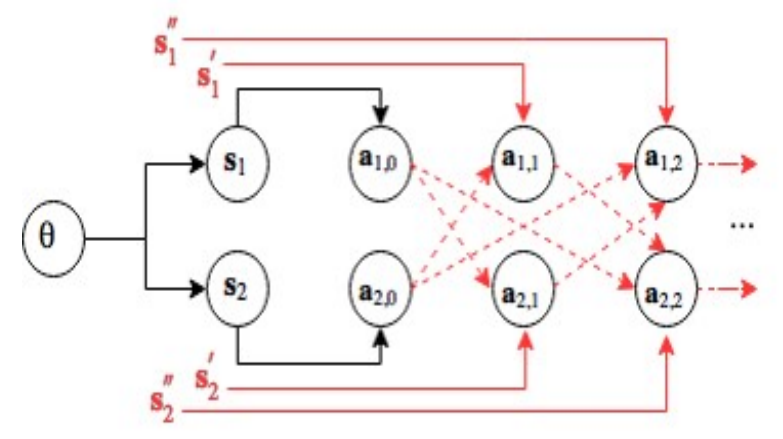
-
computational limits of Bayesian learning
Characterizing the hardness of Bayesian group decisions and reasoning in opinion-exchange networks, where agents infer from private information and histories of others' actions or beliefs [4.2, 4.3]. -
learning without recall
Explaining how simple belief-update rules arise from locally Bayesian inferences that attribute others' actions to private signals without accounting for the full history of interactions [4.4–4.6]. -
foundations of linear opinion dynamics
Deriving familiar rules for updating opinions from a model of heuristic inference and decision making [4.7]. -
switching to learn
Combining social and individual updating to learn while limiting communication [4.8]. -
cognitive biases and repeated exposure
Studying how hindsight bias impedes learning and how repetition shapes beliefs when recall is limited [4.9, 4.10].
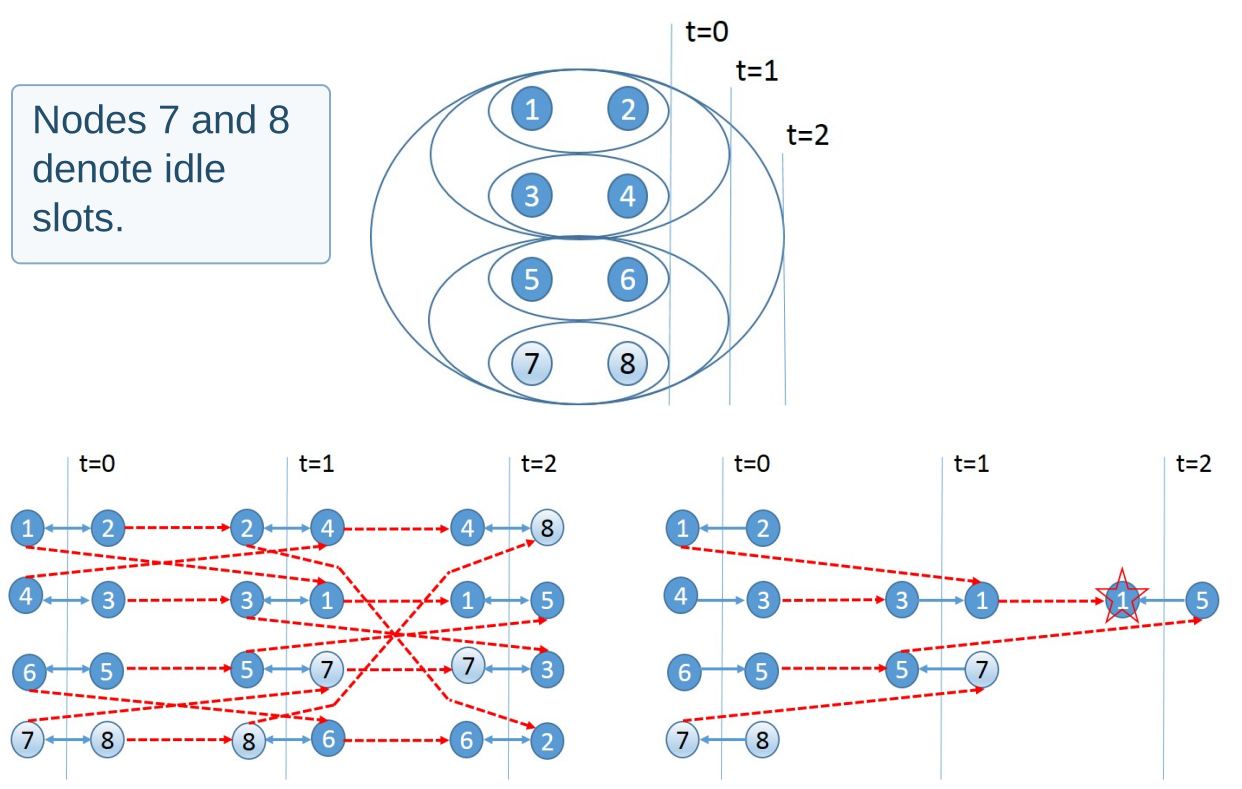
Two central issues in organizing knowledge work and supporting collective decision making are information aggregation and decision-flow architecture. My formal theories of group decision making provide structural insights into both issues and can be operationalized to avoid redundancy and increase the efficiency of group decisions among heuristic decision-makers. For example, carefully scheduled exchanges can aggregate dispersed information without repeatedly counting the same evidence.
Bayesian decision-makers avoid counting the same evidence twice, but at a computational cost: to update rationally, each member must infer which private signals are consistent with the beliefs or actions she observes, and in general networks this inference is NP-hard [4.2].
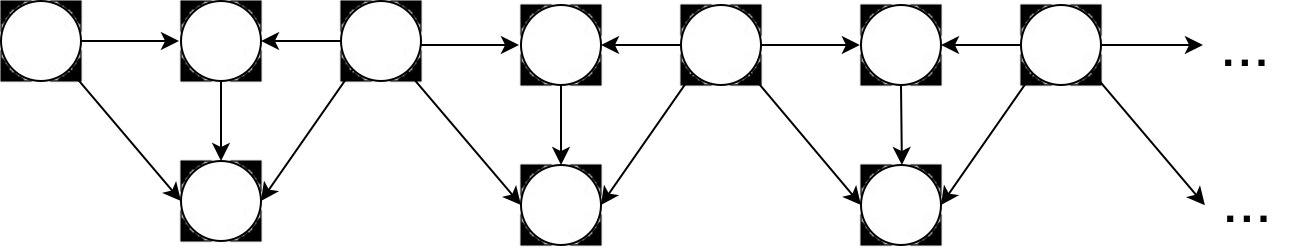
Decision-flow architecture can keep this inference tractable: when an organization grows horizontally, so that each member is influenced, directly or indirectly, by a bounded number of others, optimal decisions can be computed in polynomial time.
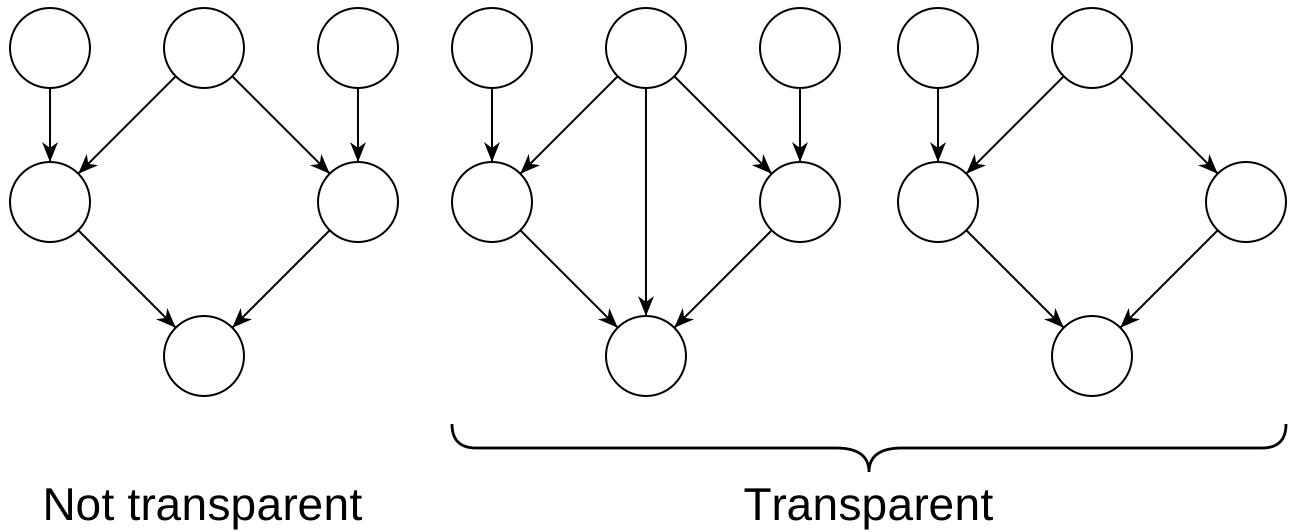
In transparent structures, such as trees, each member can combine the new information in her neighbors' beliefs to reach the belief she would hold if she saw the private signals behind them; a shared source that reaches her through more than one neighbor can break this transparency.
Related design questions arise when teams of AI agents reconcile parallel solution attempts through tree-like hierarchies.
The next two directions examine these issues when agents learn sequentially from others' actions or repeatedly exchange estimates and beliefs with their neighbors.
-
distributed estimation and learning
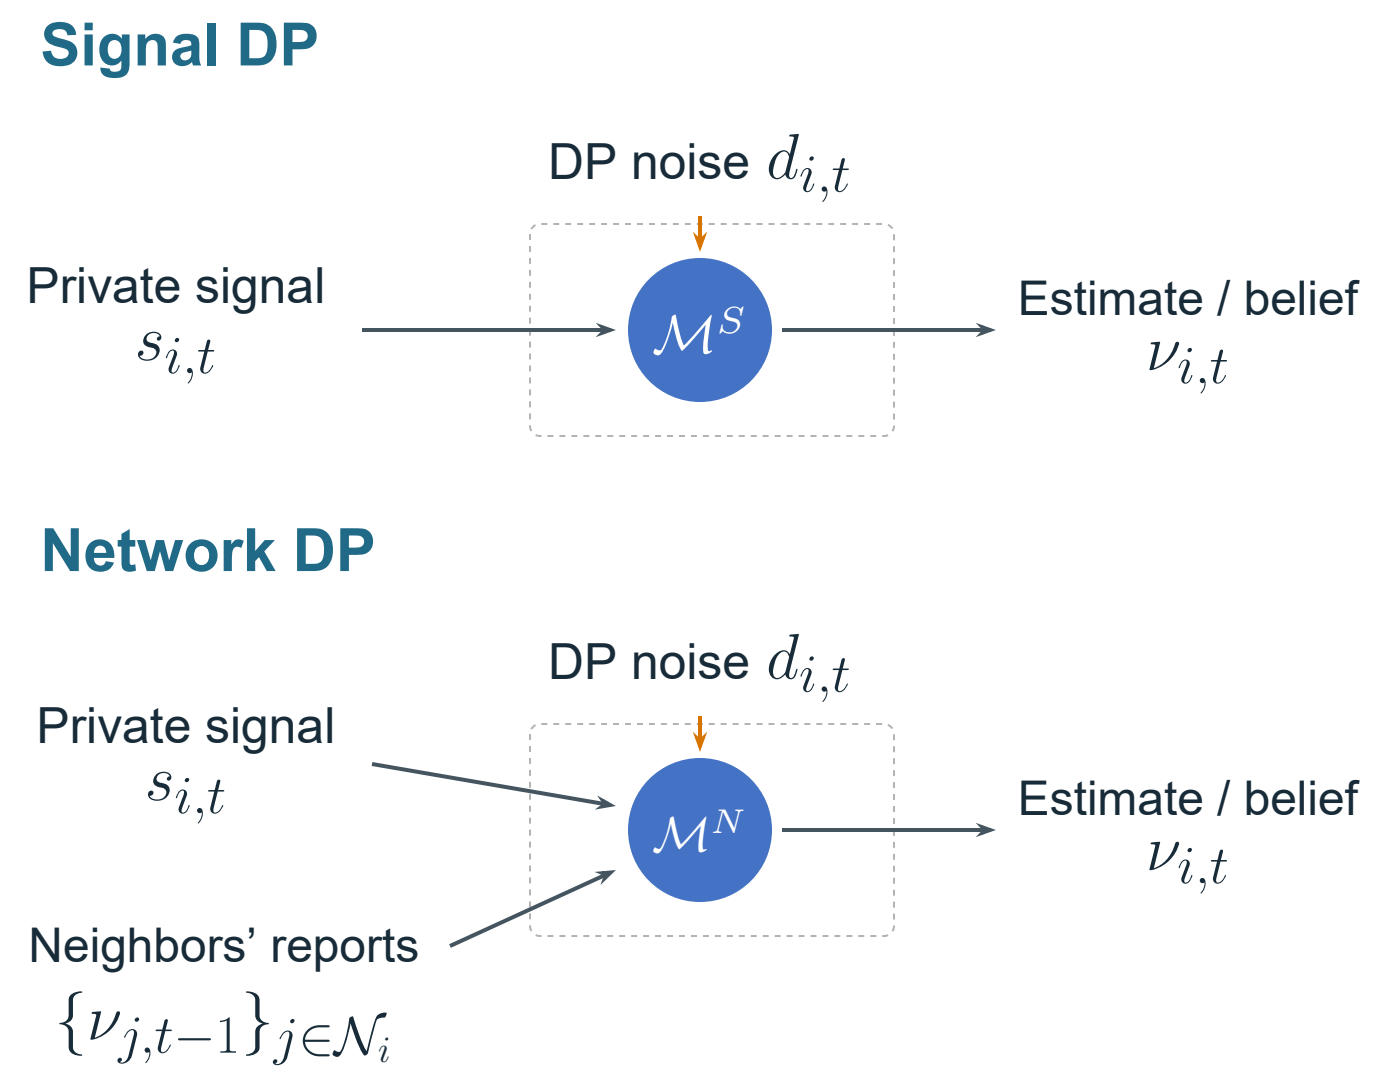
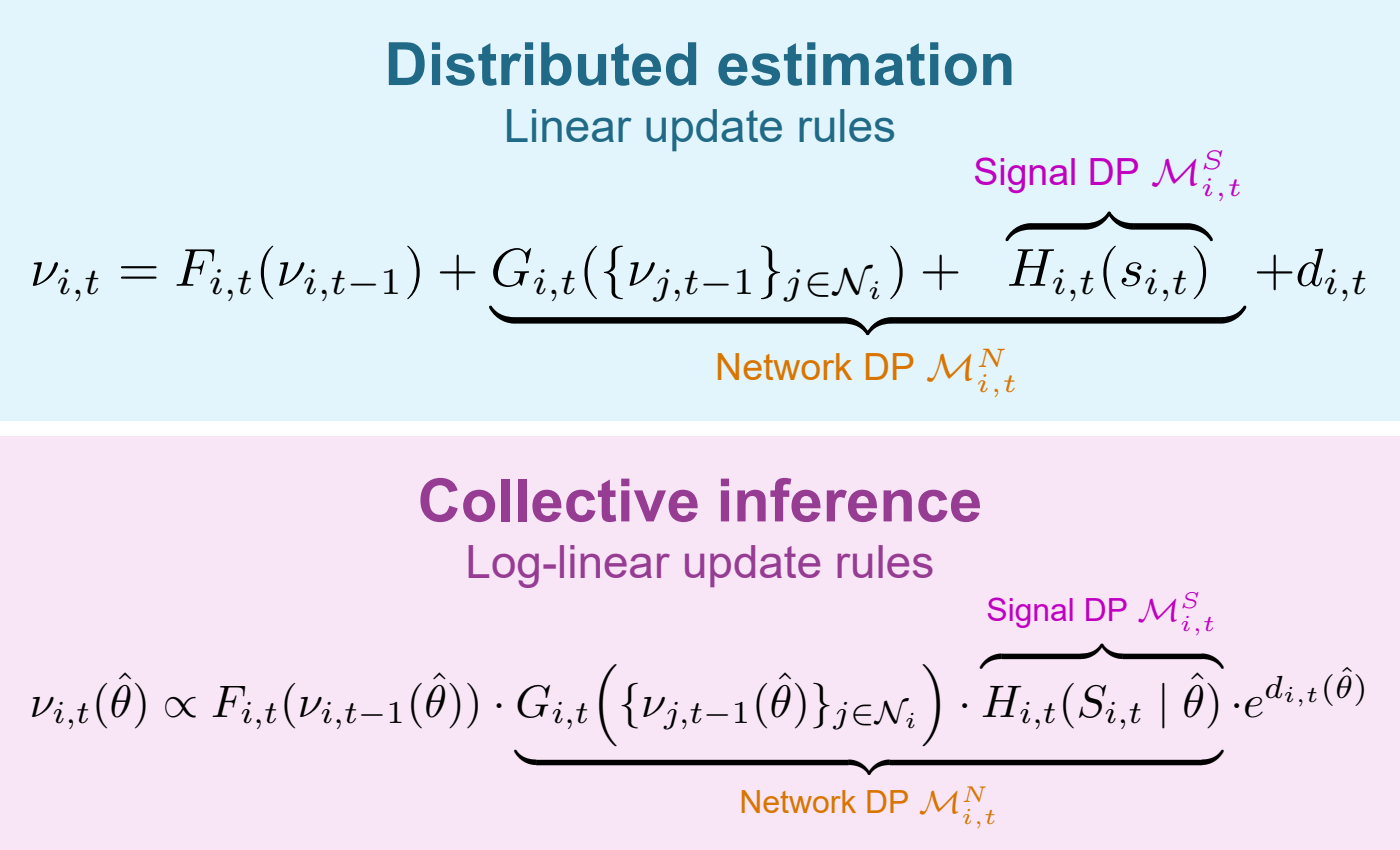
In [4.12], we study how local exchanges over heterogeneous networks aggregate observations that differ in quantity, quality, and timing, with convergence to globally efficient estimators and finite-time performance guarantees. With Marios Papachristou, I extend this framework to differentially private distributed estimation and collective inference, with explicit bounds on accuracy and convergence under privacy constraints [4.13, 4.14].
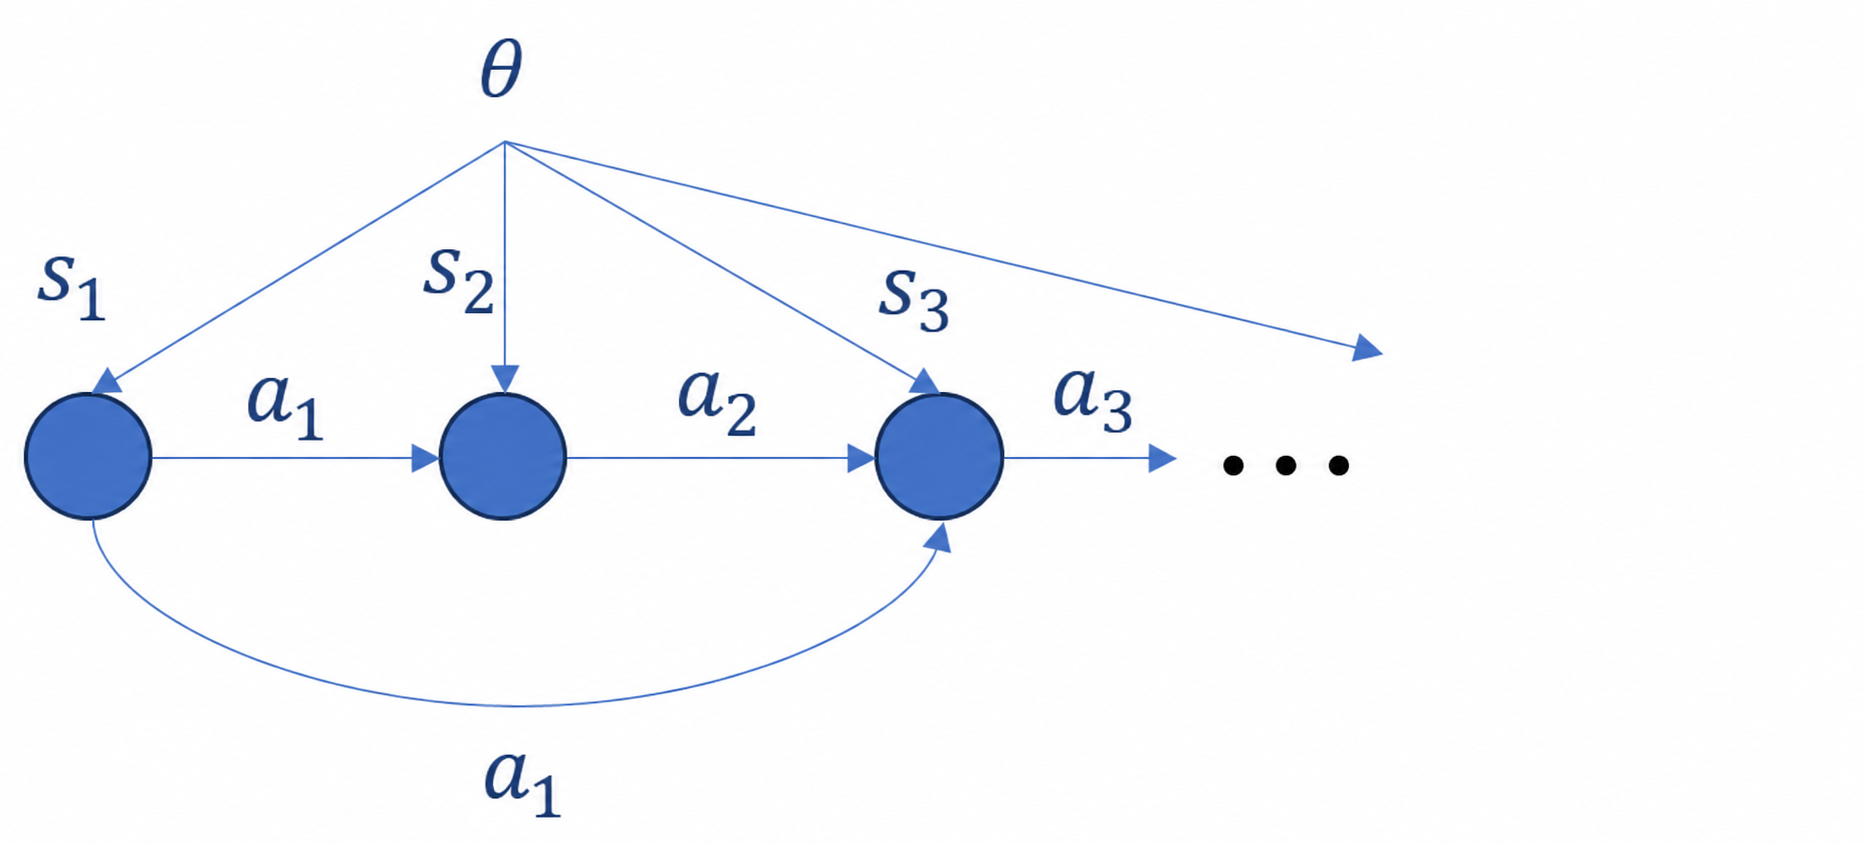
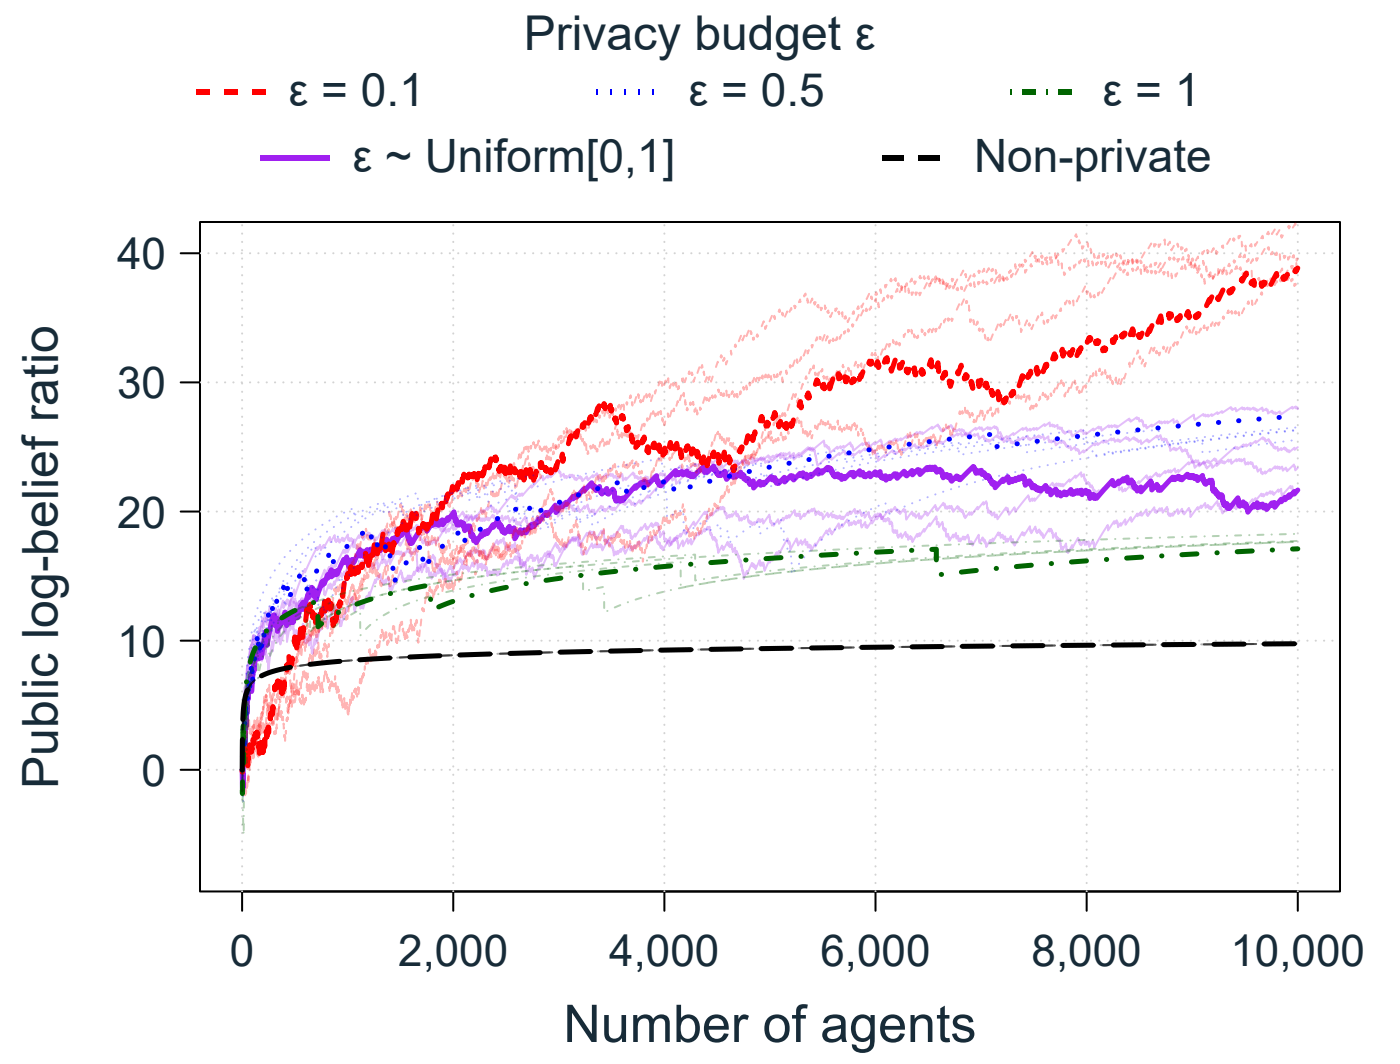
The privacy mechanisms and applications of these two directions are discussed above.
Whether social information improves collective performance depends on the task and on how communication is structured. We examine these factors in the following:
-
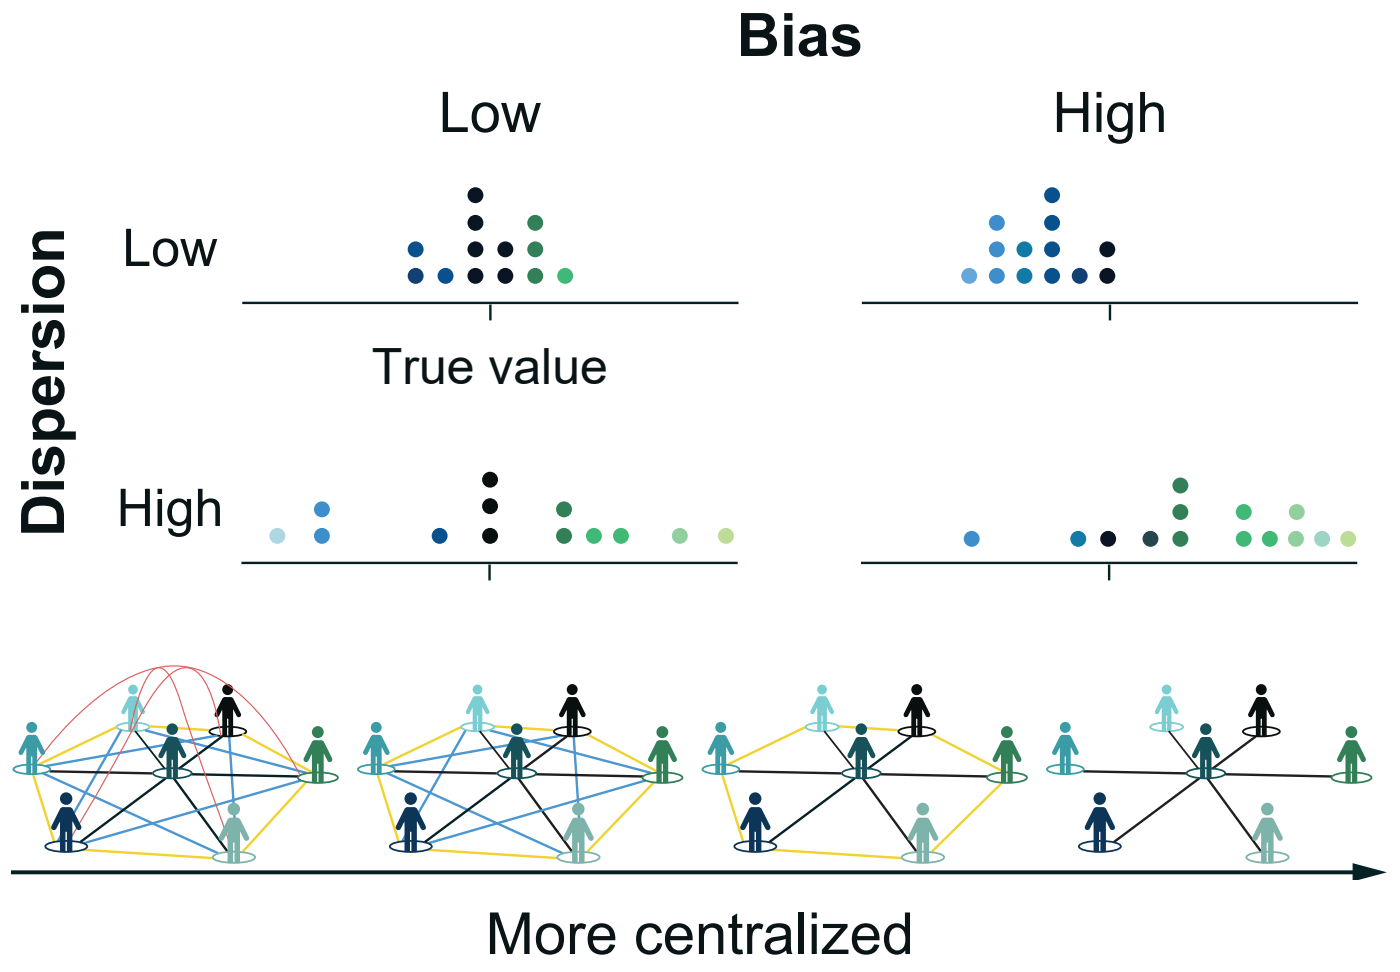
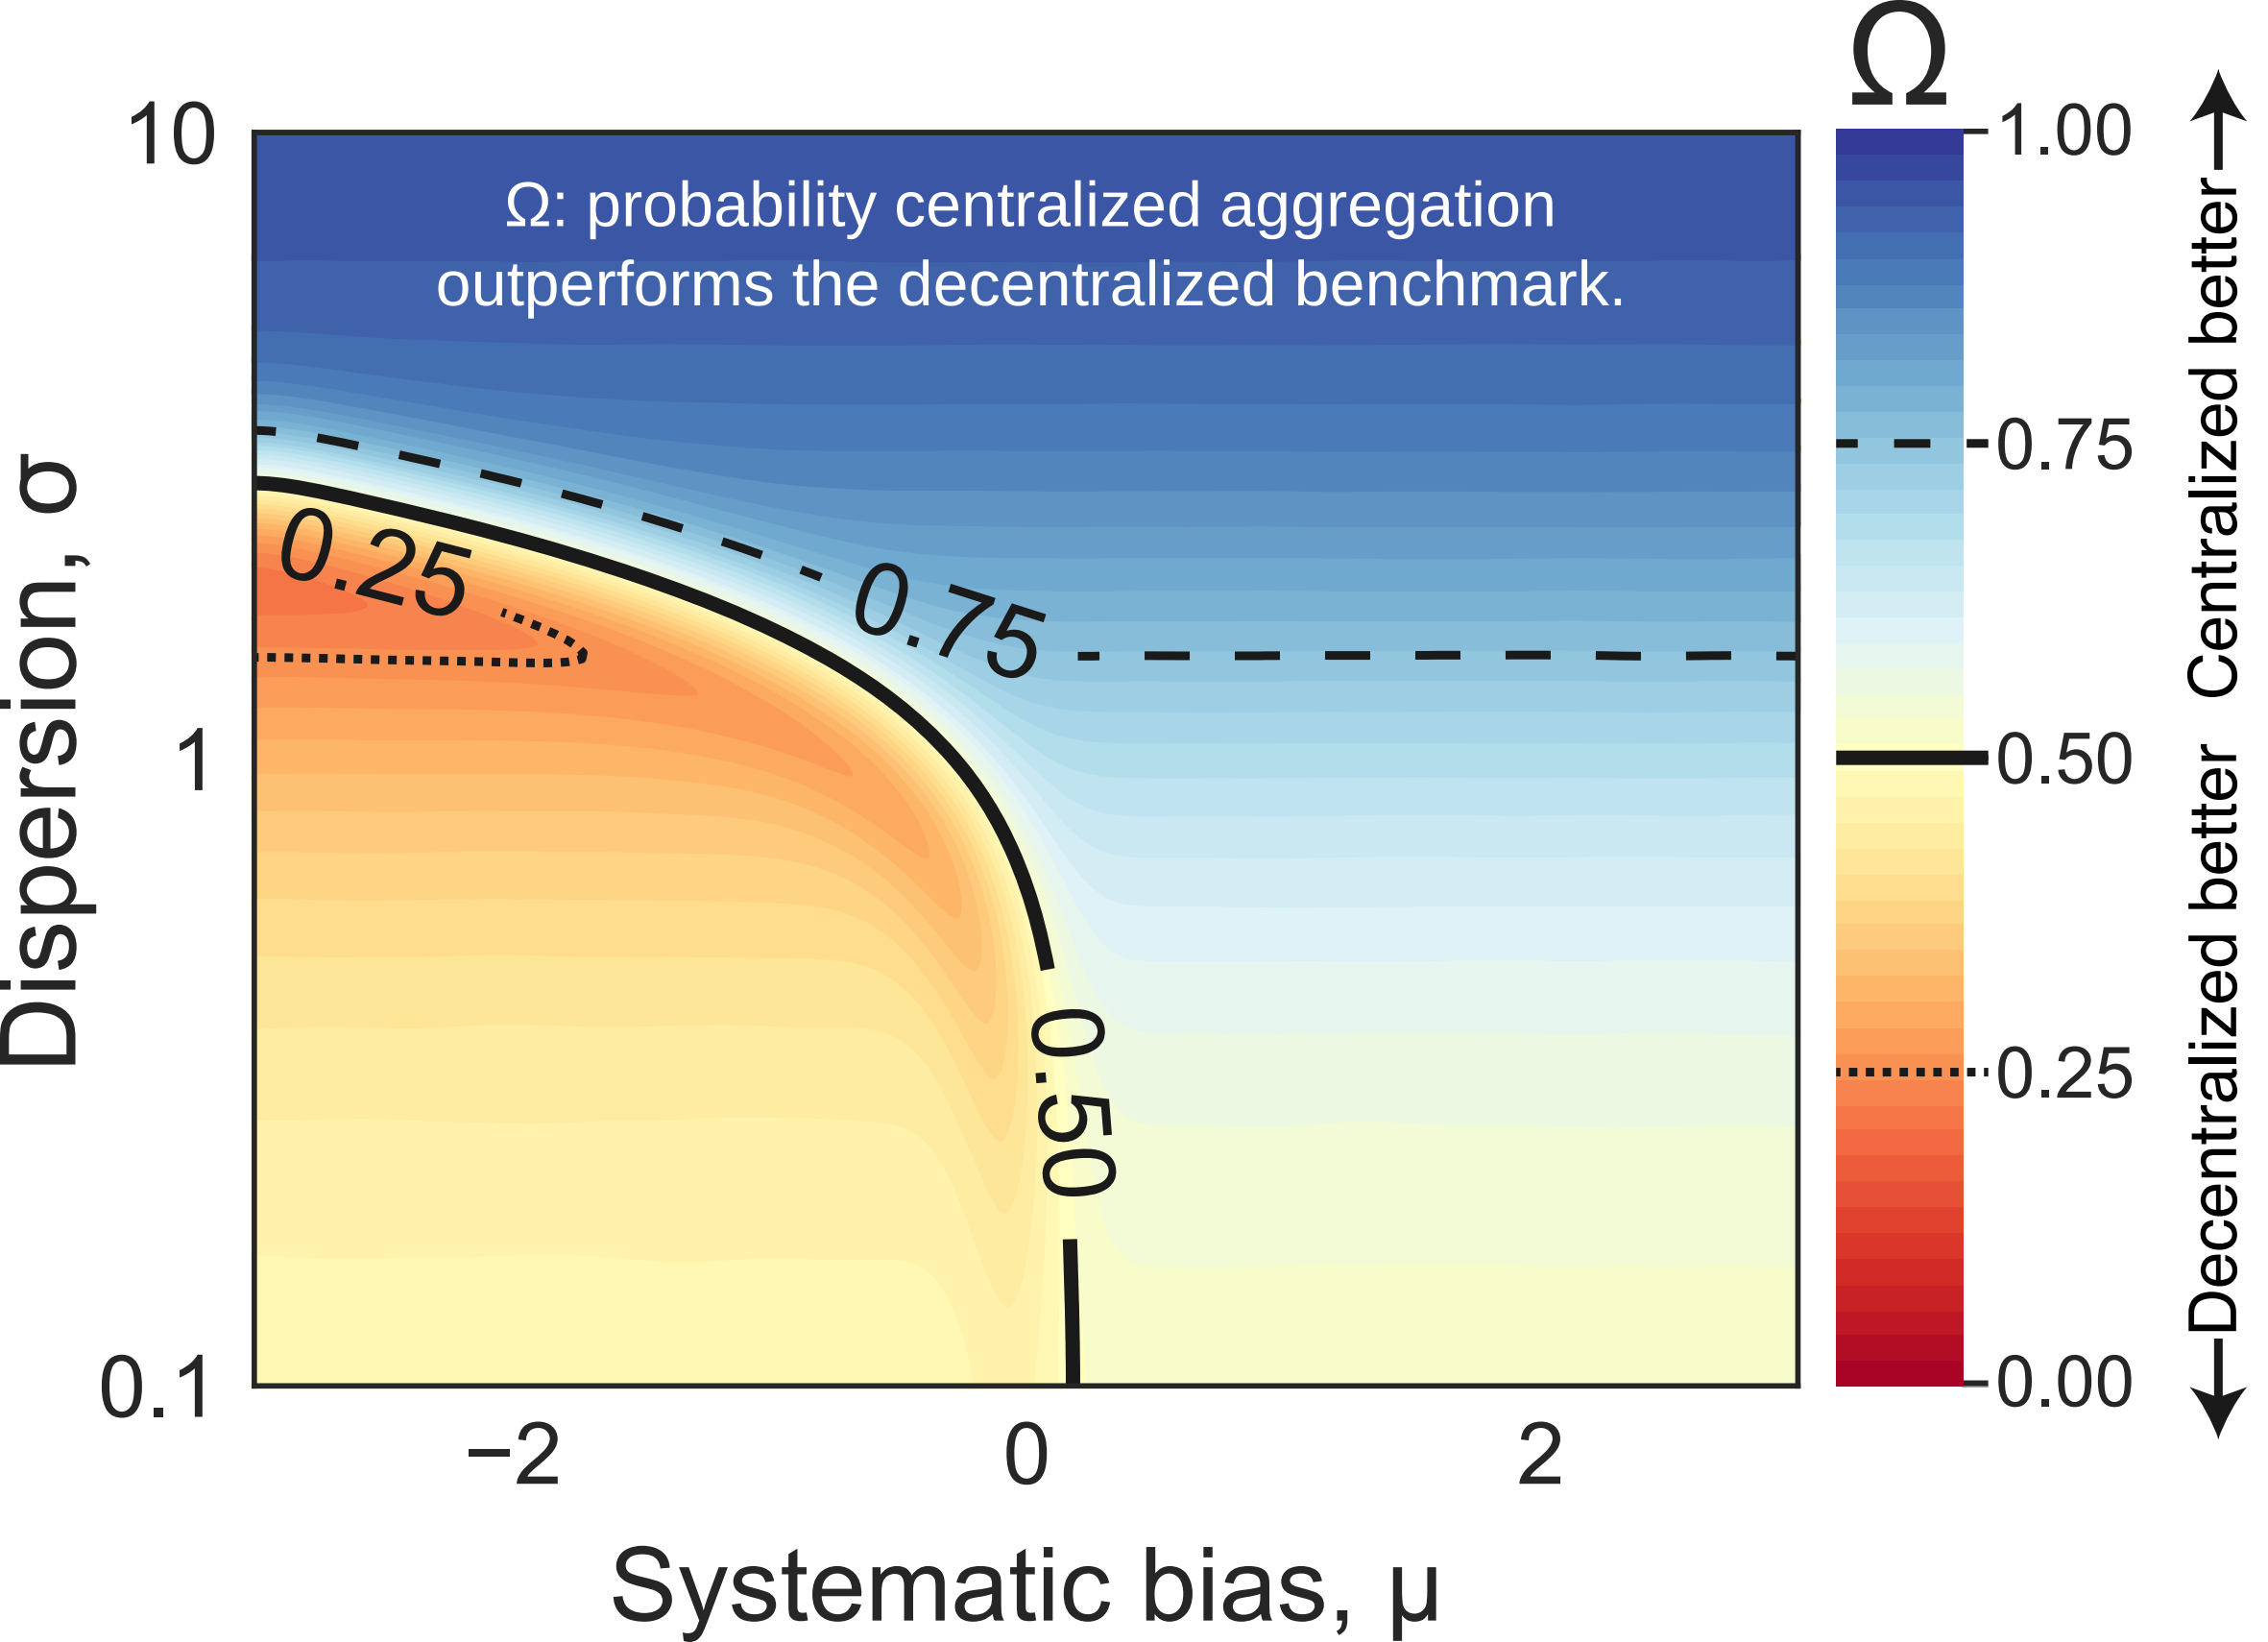
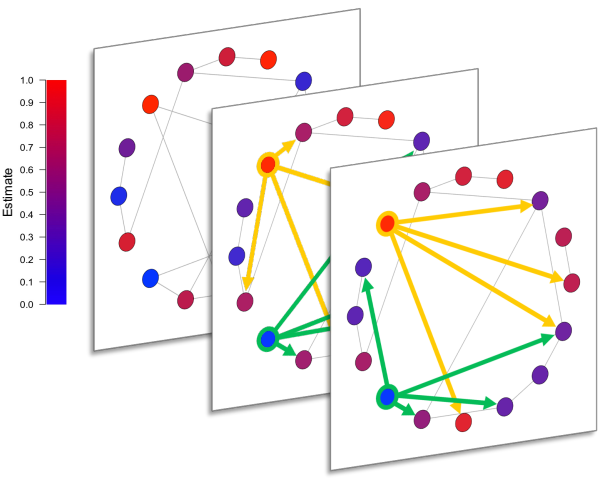
task-dependent collective intelligence
We show how the distribution of initial estimates moderates the effect of social influence on collective accuracy [4.15]. Through experiments and simulations, we also study how algorithmic mediation and rewiring of communication networks change group performance [4.16, 4.17]. -
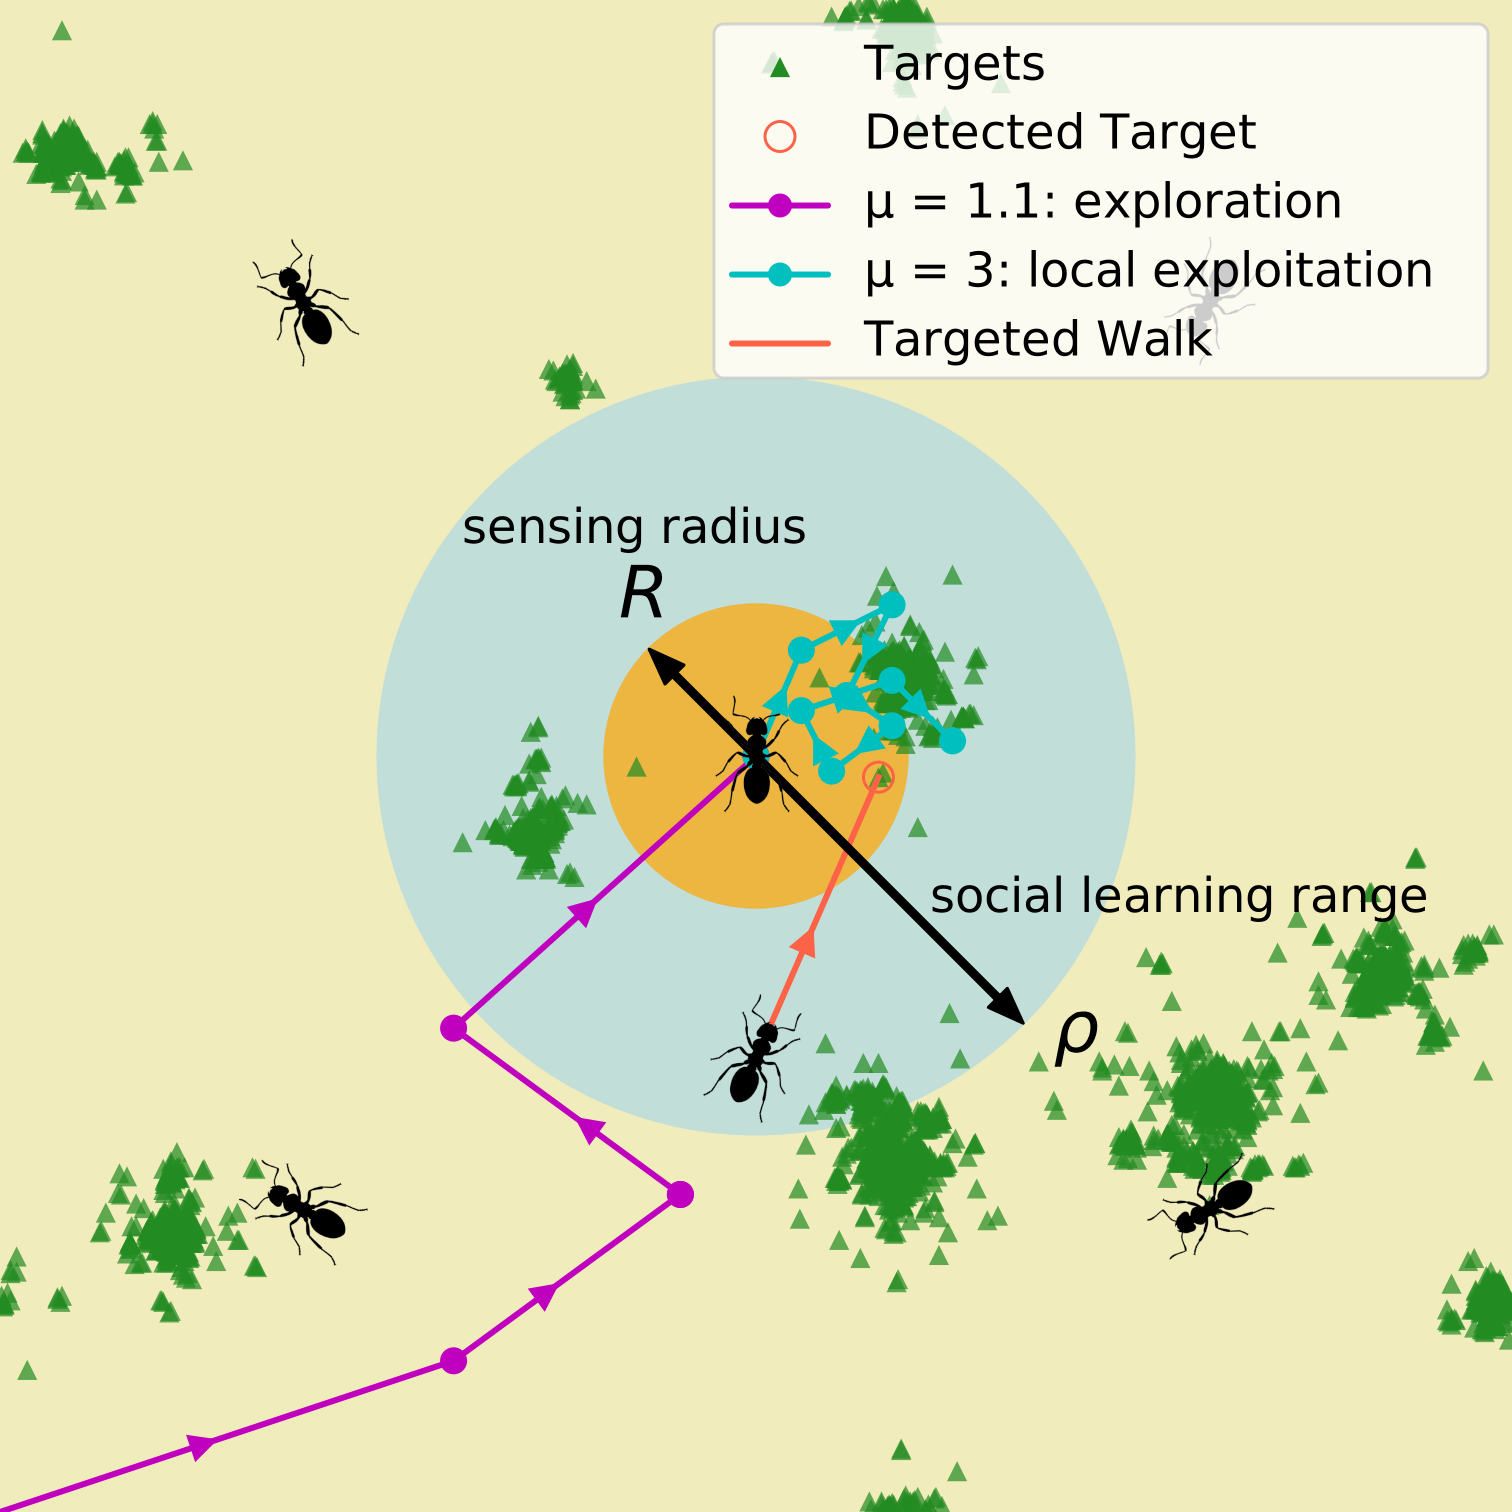
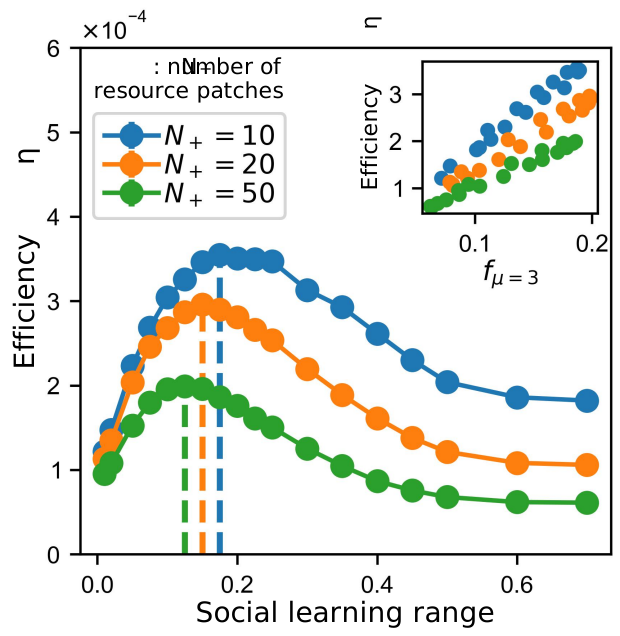
social learning in collective search
In [4.18], we study how information sharing shapes group foraging. Intermediate social learning ranges balance independent exploration with coordinated exploitation, while broader sharing can improve equity at the expense of efficiency and temporal stability.
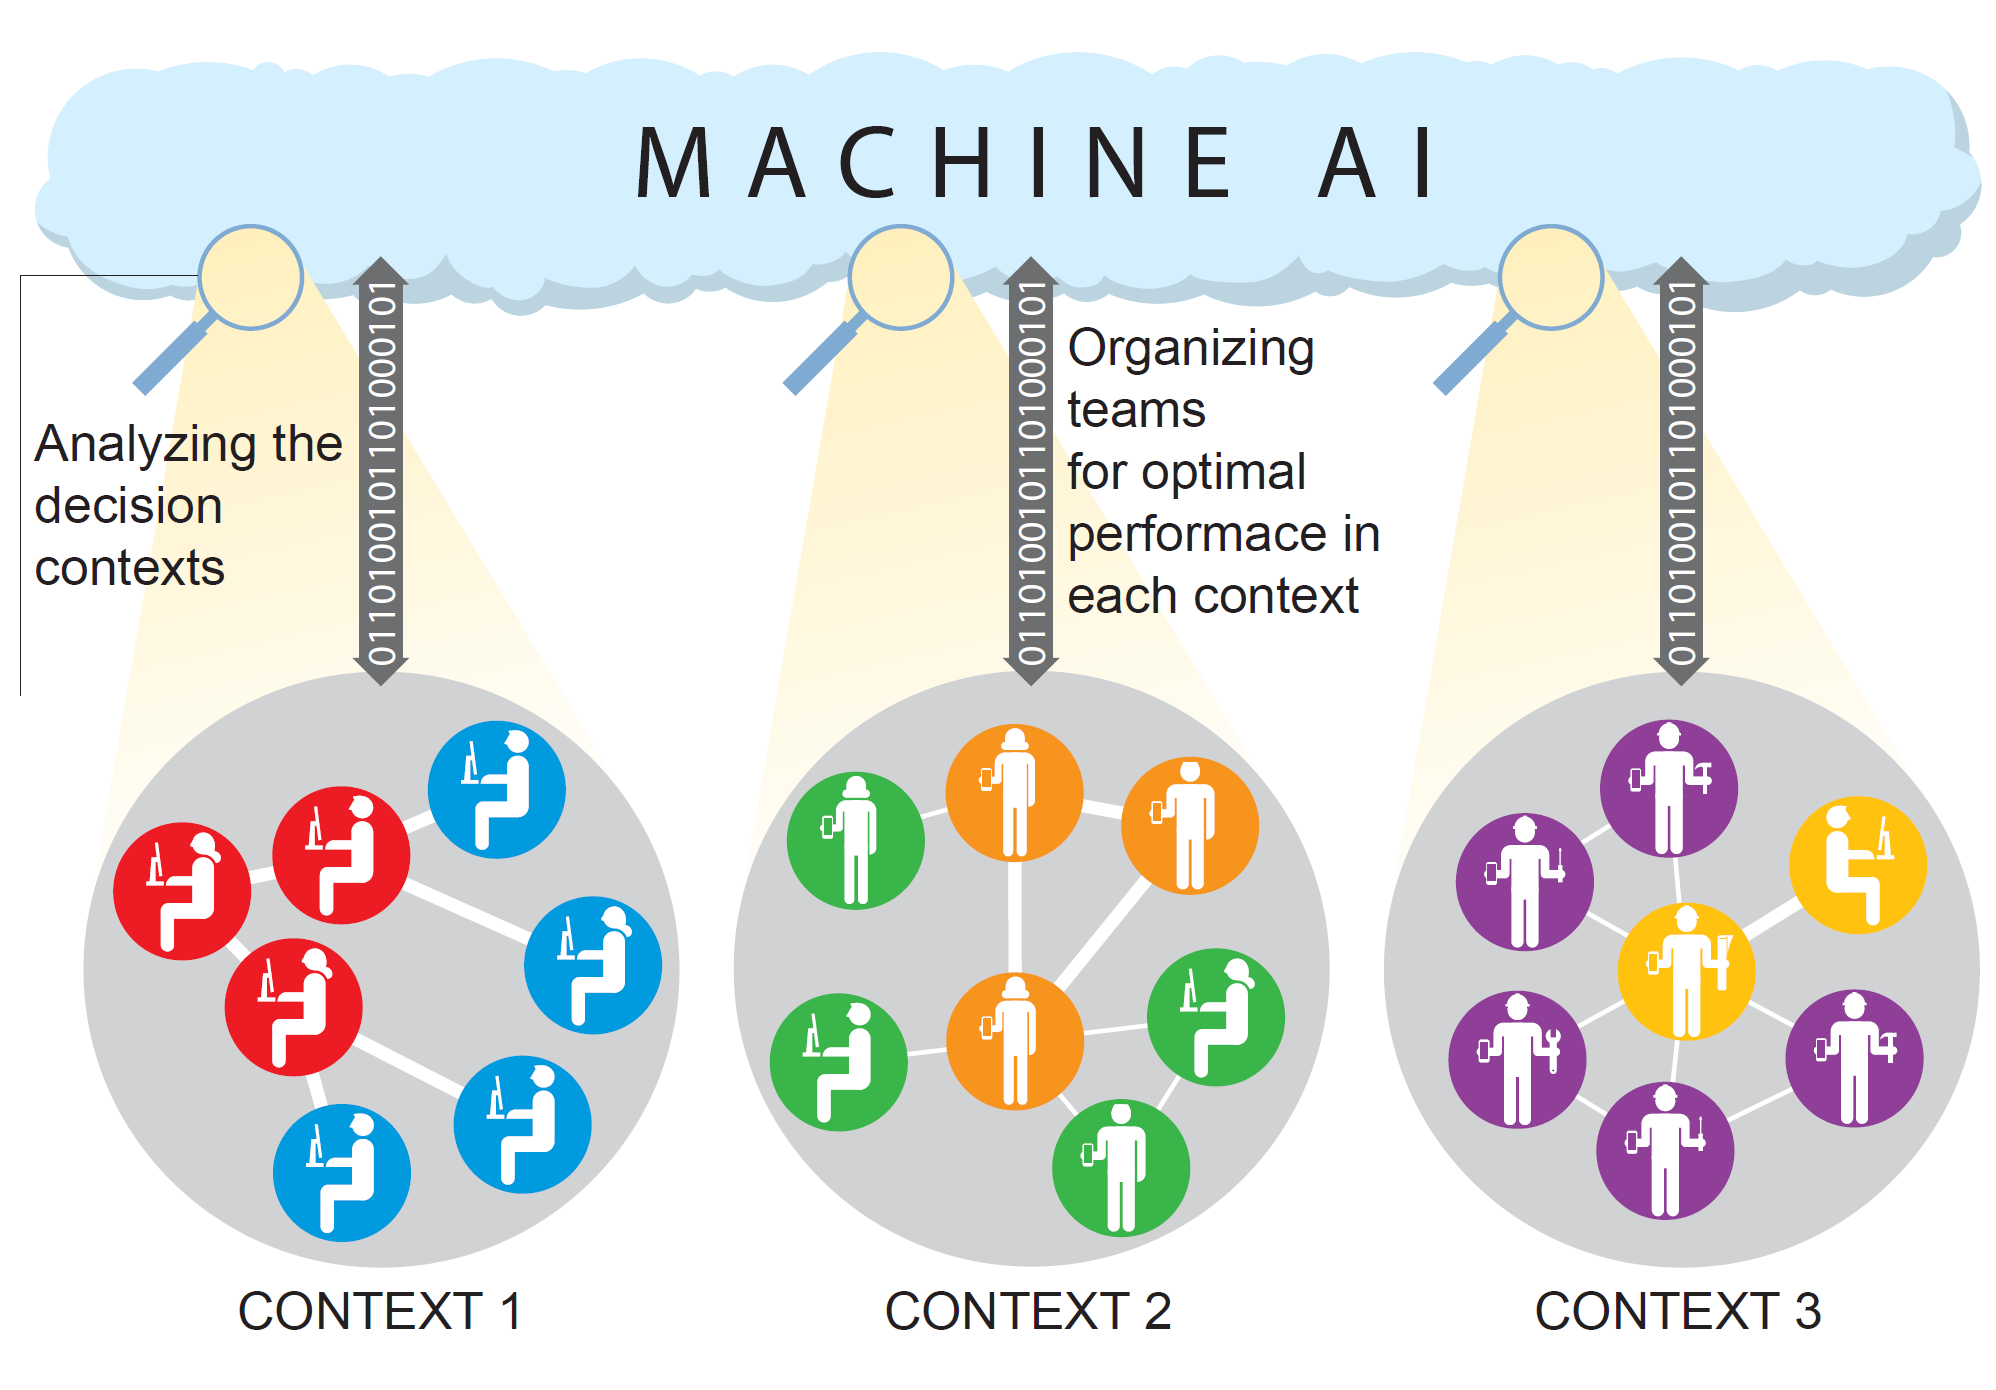
Algorithmic, computational, and optimality aspects of decision-making in organizations are vastly unexplored. There are many untapped potentials for applying these techniques to improve the operations of teams in medical, legal and other industrial decision-making organizations. By investigating the effects of heuristics and biases, we can improve the practice of social and organizational policies, such that new designs can accommodate commonly observed biases, and work well in spite of them. My ongoing work extends this agenda to human–AI collaboration in knowledge work and to collective decision making among AI agents, examining how task-dependent complementarities and communication shape decision quality and the development of human expertise.
See here for a list of the relevant publications.
Control, Analysis, and Design of Networked Dynamical Systems
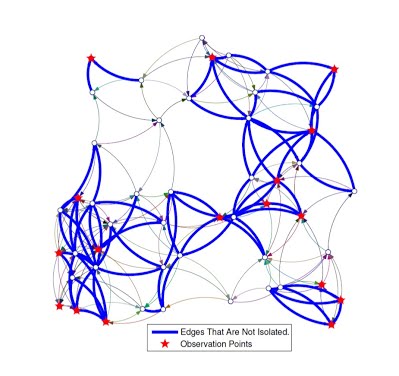
Failure detection and isolation in directed networks [5.1].
Networked dynamical systems build upon complex interactions between many co-evolving sub-components. Their industrial applications are plentiful and diverse ranging from chemical and biological processes to robotics and the power grid. My results touch upon many aspects of the analysis and design for such complex systems, including distributed detection, estimation, reliable design, and decentralized control. I have been particularly interested in the following questions:
How can we identify failures and structural variations from the observed dynamics of a limited number of output nodes?
How can we exercise control over the entire networks by accessing only a few of their input nodes?
How can we learn about environmental variables from the dispersed and disparate observations of different nodes in a network?
Tools from control theory, optimization, signal processing, statistics, graph theory, combinatorics, and discrete algorithms have enabled us to propose effective solutions to each of these problems.
Some highlights from our results on the analysis and design of networked dynamical systems are as follows:
Efficient Placement of sensors for detection and isolation of failures (submodular maximization) [5.1]
Detection and isolation of link failures based on the observed outputs (linear systems theory) [5.1]
Distinguishing network structures based on their nodal dynamics (algebraic graph theory) [5.2]
Protecting structural controllability against link and node failures (graph theory, combinatorics) [5.3]
Efficient methods to rank links and nodes for the preservation of structural controllability (graph theory, combinatorics) [5.3]
Efficient placement of actuators for optimal control performance (submodular maximization) [5.4,5.5]
Learning from intermittent streams of heterogeneously correlated data (distributed estimation, learning theory, Bayesian statistics) [5.6]
Today cars and mobile phones rely on large arrays of sensors and actuators for their operations. Robotic networks are employed to manage massive inventories efficiently, at a low cost. The analytical tools that are developed in the study of complex network systems will pave the way for the Internet of Things, Cyber-Physical Systems, and other disruptive technologies of future.
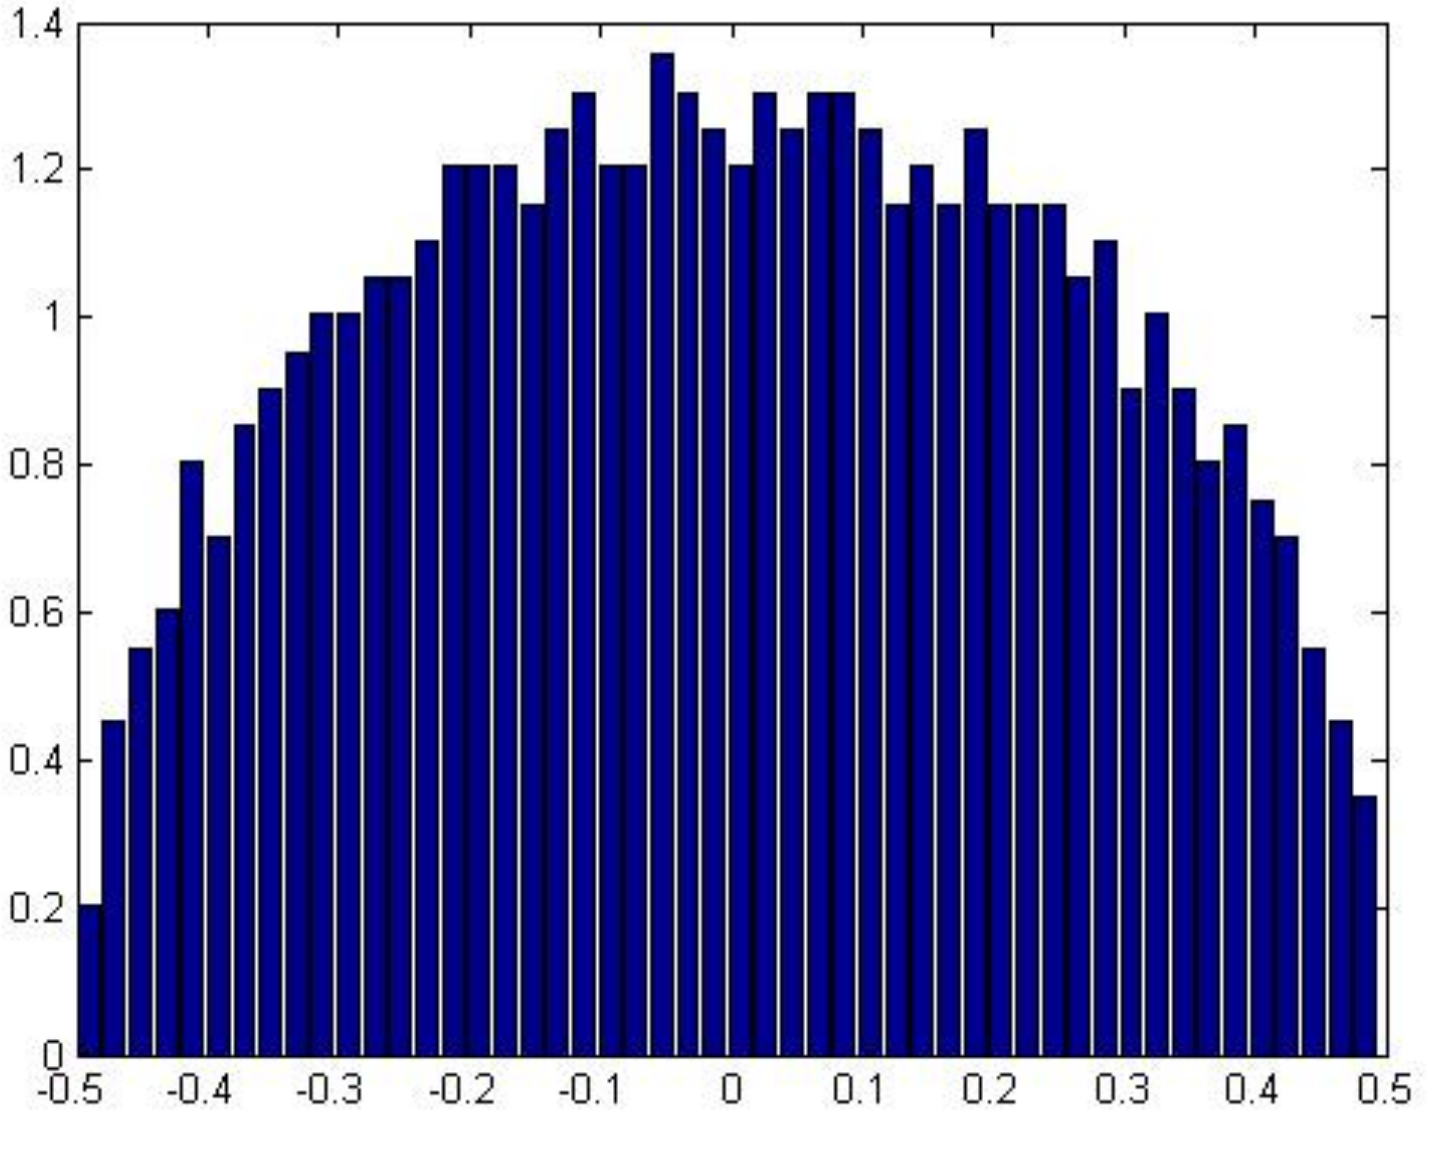
Semicircle spectrum of a random network [5.9].
Some of my more recent works in this area are focused on developing tools that pioneer applications of random matrix theory in the modeling and analysis of large-scale networks and dynamic systems. Such tools have great potential for addressing questions whose depth and analytical complexity have impeded researchers so far. They are also very versatile and expressive when it comes to modeling and explaining structural features of very large-scale systems such as robotic swarms or the extremely high dimensional data sets that arise in the study of the Internet and online social networks. Some of my main results so far are:
Limiting spectral moments of random matrices with rank one pattern of variance [5.7]
Limiting spectral moments of random graphs with specified expected degrees (the Chung-Lu model) [5.8]
Theoretical justification for the quasi-triangular spectrum of power-law networks (reported in empirical literature) [5.8]
H2 norm and the spectrum of the controllability Gramian of random linear systems [5.9]
The theoretical insights from random matrix theory are complementary to what we learn from the theory of random graphs or systems and control theory. Random matrix theory offers new ways of thinking about the design and analysis of massive scale systems.
See here for a list of the relevant publications.
Design, Analysis, and Tuning of Feedback Controllers
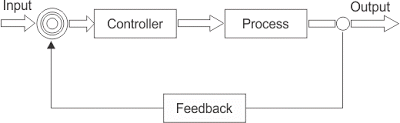 The versatility and simplicity of proportional, integral and derivative (PID)
actions have made them the most common form of feedback control, and almost
universal all across the agriculture, transport, chemical and manufacturing
industries, or even telecommunications and web services. Our ability to efficiently
tune these controllers is key to their widespread adoption. My collaborators and
I have advanced the state of the art in process control by proposing new ways of
tuning feedback controllers. Our methods focus on explicit characterization of
feasible domains in the control parameter space. Tools from complex analysis allow
us to study the root boundaries of various polynomials that arise in the study of
the feasible domains.
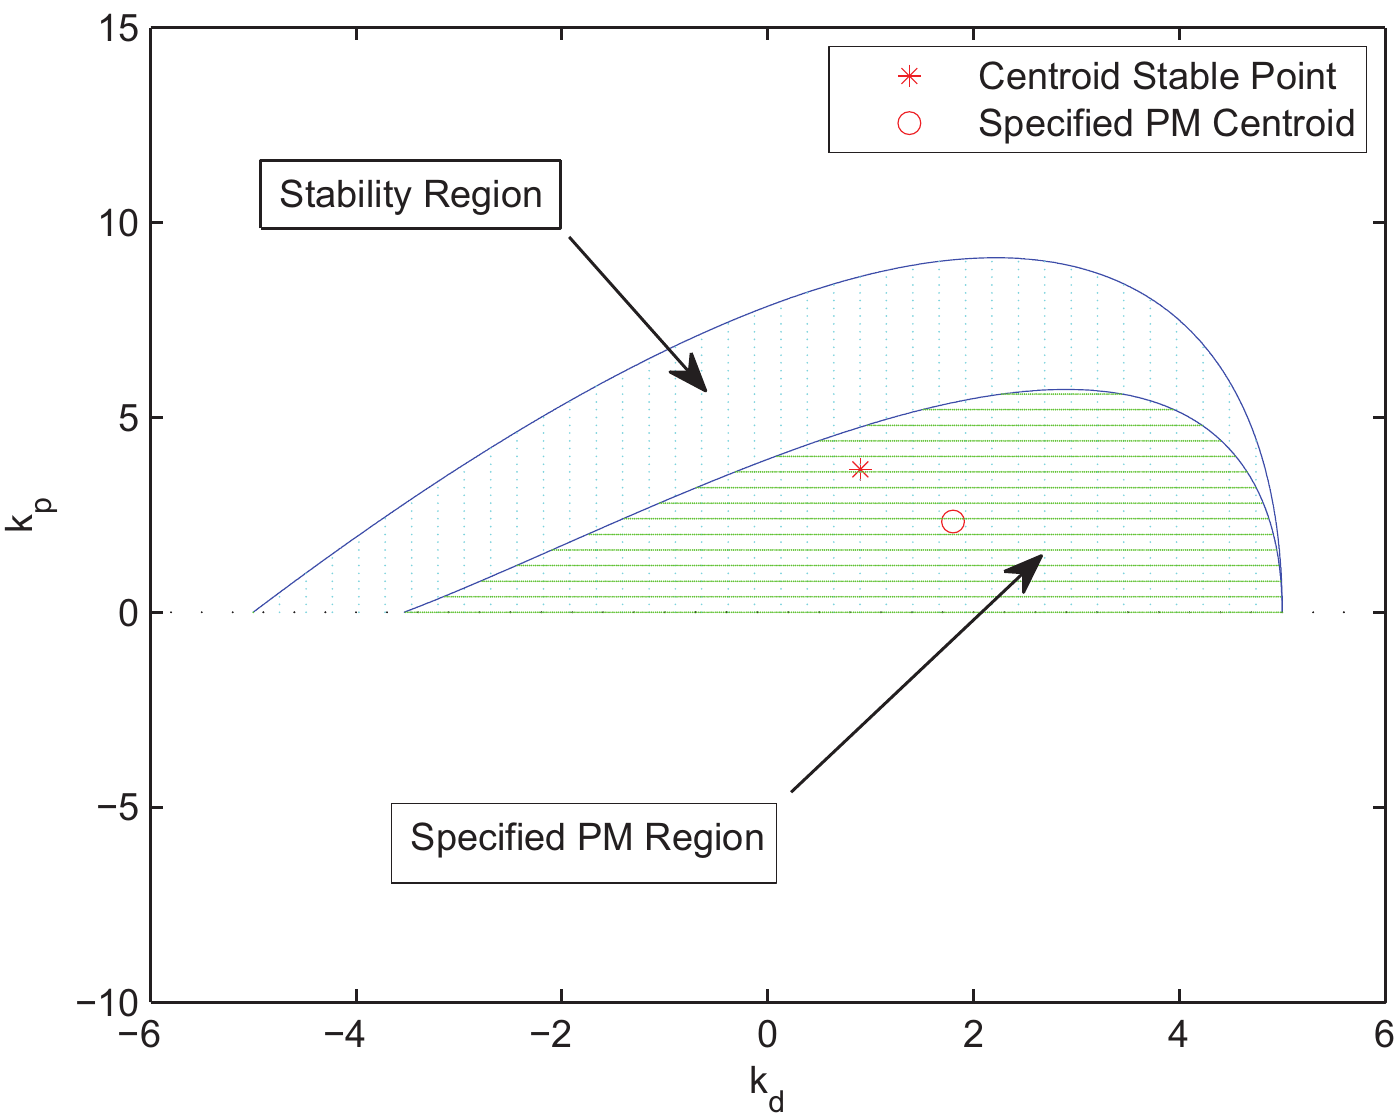
Centroid tuning with a phase margin (PM) constraint [6.3].
Fractional order control builds on a natural generalization of the integral and derivative feedback actions based on fractional order differential operators. We have successfully applied several of our techniques in the design and stabilization of fractional order controllers. Here are some of the highlights from our results on the design and tuning of feedback controller:
Constrained tuning and parameter optimization over the feasible regions [6.1, 6.2]
Using the stability region centroids for robust and non-fragile stabilization [6.3,6.4]
Stability regions for fractional-order controllers and their integer approximations [6.5]
Although I no longer follow this line of work, the study of feedback control early in my research career has influenced my understanding of large-scale complex systems.
Ubiquitous adoption of proportional and integral actions for feedback control can be traced back to the industrial revolution. Improved tuning is essential as we encounter new challenging control applications in complex industrial processes. Fractional order controllers offer additional degrees of freedom in tuning, while preserving the essential structure of the PID feedback which is so popular in industrial applications.
See here for a list of the relevant publications.